Executive Overview
For decades, the field of artificial intelligence was largely confined to digital environments. We watched algorithms master chess, generate photorealistic art, and process natural language with breathtaking fluency. Yet, bringing AI into the physical world—a discipline increasingly known as Physical AI or embodied robotics—presents an entirely different magnitude of challenge.
Recognizing an object visually does not tell a robot how that object will behave when touched. Consider a deceptively simple task: pushing a small cardboard box across a laboratory floor to a precisely marked position. To a human, this is trivial. To a robot, identifying the box is merely the opening hurdle. Training an effective robotic policy requires a rich, multi-layered data representation that encodes the object’s exact 3D shape, its contact surfaces, its mass, its friction coefficients, and its physical behavior under force.
As the robotics industry accelerates toward autonomous manipulation and generalized physical agents, a critical bottleneck has emerged: the scarcity of simulation-ready 3D data. While massive repositories like Objaverse provide hundreds of thousands of visual models, they frequently lack the foundational physical properties required for physics engines. This comprehensive analysis explores the anatomy of training data for Physical AI, the critical distinctions between visual and collision geometries, the role of semantic labeling, and the persistent hurdle of the "reality gap" in simulation-to-real (sim-to-real) transfer.
Detailed Chronology: The Evolution of Simulation and Embodied Data
To understand how the robotics community arrived at current data pipelines, it is necessary to trace the technical milestones that shaped modern physics simulation and asset pipelines.
- The Early Era of Parametric Modeling (Pre-2010s): Early robotic simulations relied on heavily simplified geometric primitives—cylinders, cubes, and spheres—coupled with manually tuned physics parameters. Training generalized behaviors was nearly impossible due to the lack of diverse, high-fidelity 3D assets. Robots were programmed via hardcoded kinematics rather than learned data-driven policies.
- The Rise of Unified Robot Description Formats (2010s): The widespread adoption of formats such as the Unified Robot Description Format (URDF) and MuJoCo XML brought structure to robotics simulation. Engineers could explicitly define links, joints, visual meshes, and collision geometries. However, asset creation remained an excruciatingly manual, artisanal process.
- The Big-Data 3D Explosion (2022): The release of large-scale 3D asset repositories marked a turning point. Notably, the Objaverse 1.0 project introduced over 800,000 3D models complete with descriptive captions, tags, and animations. While this solved the visual scarcity problem for computer vision, it exposed a glaring data gap: these models possessed zero intrinsic physical properties, rendering them useless for interactive robotics without extensive manual remediation.
- The OpenUSD Standard and Modern Pipelines (2023–Present): Platforms like NVIDIA’s Isaac Sim integrated advanced frameworks such as OpenUSD (Universal Scene Description) and USD Asset Structure 3.0. This allowed developers to ingest complex meshes, STEP files, and multi-format robot descriptions while decoupling visual appearance from collision and physics properties. Concurrently, automated physics-derivation tools (such as those developed by firms like Physicl) began emerging to automatically compute mass, friction, and inertia from raw geometric inputs.
Supporting Context & Metrics: Anatomy of a Simulation-Ready Asset
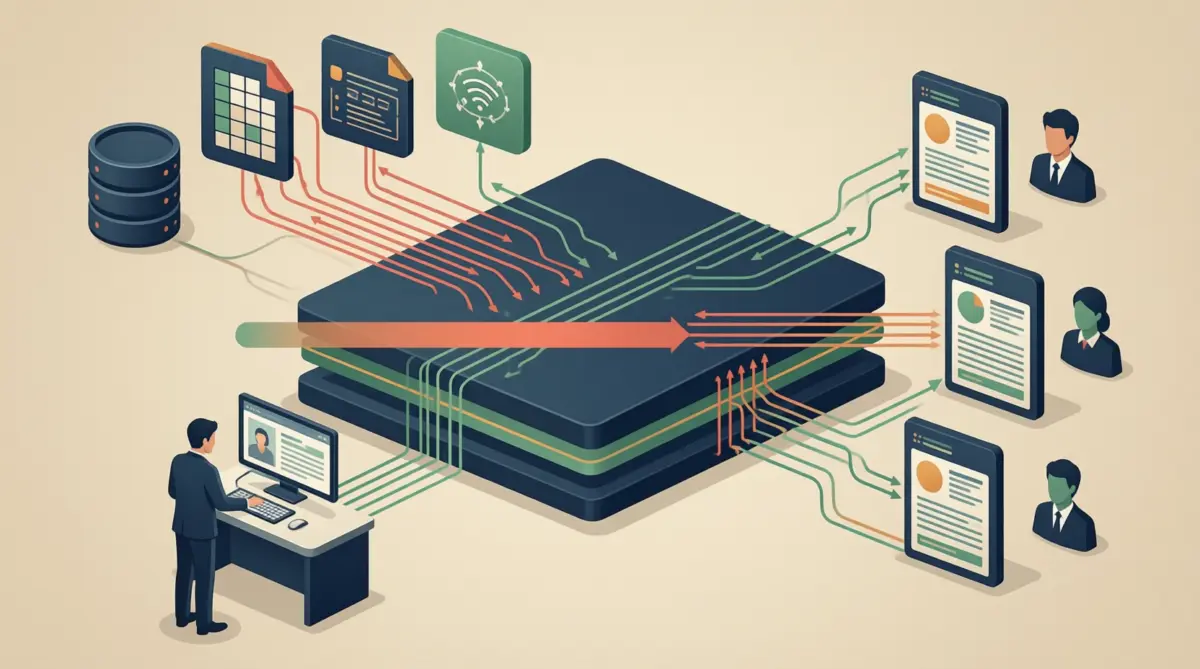
Training a robot for physical interaction requires three distinct data layers working in concert: 3D geometry, physical properties, and semantic information.
1. 3D Geometry: Visual vs. Collision Models
A foundational error in early robotics simulation was attempting to use the same 3D mesh for both rendering and physics calculation. As documented in NVIDIA’s Isaac Sim guidelines, a robot link’s URDF visual tag describes its visible mesh and surface material, whereas its collision tag describes the simplified geometry used by the physics engine (such as PhysX) to calculate contact forces.
For our box-pushing example, a high-polygon visual mesh with complex curves and textures would grind a physics engine to a halt if used for collision detection. Conversely, a simplified bounding box optimized for collision calculations would fail to register subtle physical interactions. Separating these layers allows developers to maintain performance without sacrificing visual fidelity. Furthermore, modern layered asset structures permit engineers to modify collision filtering or joint settings independently of base geometry.
2. Physical Properties: Mass, Inertia, and Friction
Shape alone does not specify mass or inertia. A hollow plastic box and a solid block of lead may share identical 3D geometries, but their physical behaviors under an applied force are radically different.
Physical parameters—including mass distribution, center of mass, and friction coefficients—must be explicitly defined for every link in a simulation environment. While some modern asset-preparation pipelines attempt to derive these properties automatically from raw inputs, engineers must treat derived values as hypotheses rather than absolute truths. A mismatch between simulated physics and real-world physics is the primary breeding ground for simulation failure.
3. Semantic Information: Contextualizing Interaction
Semantic data records what an asset or attribute actually means for interaction. For instance, data labels such as Graspable: false or Interactive: door serve entirely different functions. One denotes a manipulability constraint, while the other triggers a specific kinematic or articulated response.
Crucially, a semantic label like "door" does not inherently supply a mass value, a hinge joint type, or a collision surface. Semantics provide contextual meaning, but geometry and physical parameters supply the mathematical foundation required by the physics engine.
Official Statements and Technical Insights
The challenges of transitioning from pure perception to physical interaction have drawn extensive commentary from leading researchers and systems architects.
"Recognizing an object doesn’t tell a robot how that object will behave when touched… For physical AI, the data must support interaction as well as perception."
This core tension highlights why computer vision datasets (like ImageNet or standard 3D vision benchmarks) are fundamentally insufficient for robotics. A model can classify a chair with 99% accuracy, but if the training pipeline lacks data regarding the chair’s weight, center of gravity, and upholstery friction, an autonomous agent will fail to interact with it safely in the real world.
Addressing the persistent threat of the "reality gap," pioneering research into dynamics randomization (such as the landmark sim-to-real transfer studies published in academic literature) demonstrated that models trained exclusively in simulation can successfully transfer to real hardware if the simulation environment deliberately introduces noise and variation into the physics parameters during training. By forcing an agent to adapt to fluctuating friction, variable masses, and stochastic forces, the learned policy becomes robust enough to withstand real-world imperfections.
However, researchers issue a firm caveat: while dynamics randomization works well for specific bounded tasks (such as robotic-arm object pushing), it is not a silver bullet. No single simulation-trained asset or policy can guarantee zero-shot transfer across every conceivable physical domain without empirical real-world validation.
Future Outlook: The Next Frontier for Physical AI
As we look toward the horizon of humanoid robotics and autonomous physical agents, the data landscape is undergoing a profound structural shift. The industry is moving away from purely aesthetic 3D model aggregation toward simulation-ready data engineering.
Companies are increasingly building specialized asset pipelines that embed physics metadata directly into 3D repositories at scale. This includes automated generation of collision meshes, machine-learning-derived inertia tensors, and standardized semantic tagging designed explicitly for manipulation tasks.
Over the coming years, we can expect the maturation of automated asset cleansing tools that bridge the chasm between raw CAD/USD files and high-performance physics engines. Ultimately, the success of Physical AI will not be measured merely by how many millions of objects an AI can recognize, but by the fidelity, completeness, and physical accuracy of the simulation environments in which those agents are forged. Matching the data directly to the physical interaction remains the ultimate crucible for the next generation of embodied intelligence.