Executive Overview
In the high-stakes world of e-commerce, few rituals are as predictable—or as futile—as the quarterly attribution debate. Around glass-walled conference rooms and Slack channels alike, marketing teams lock horns over the superiority of last-click versus data-driven models, agonizing over fractional percentage shifts in channel credit. Yet, these fierce arguments fundamentally miss the point.
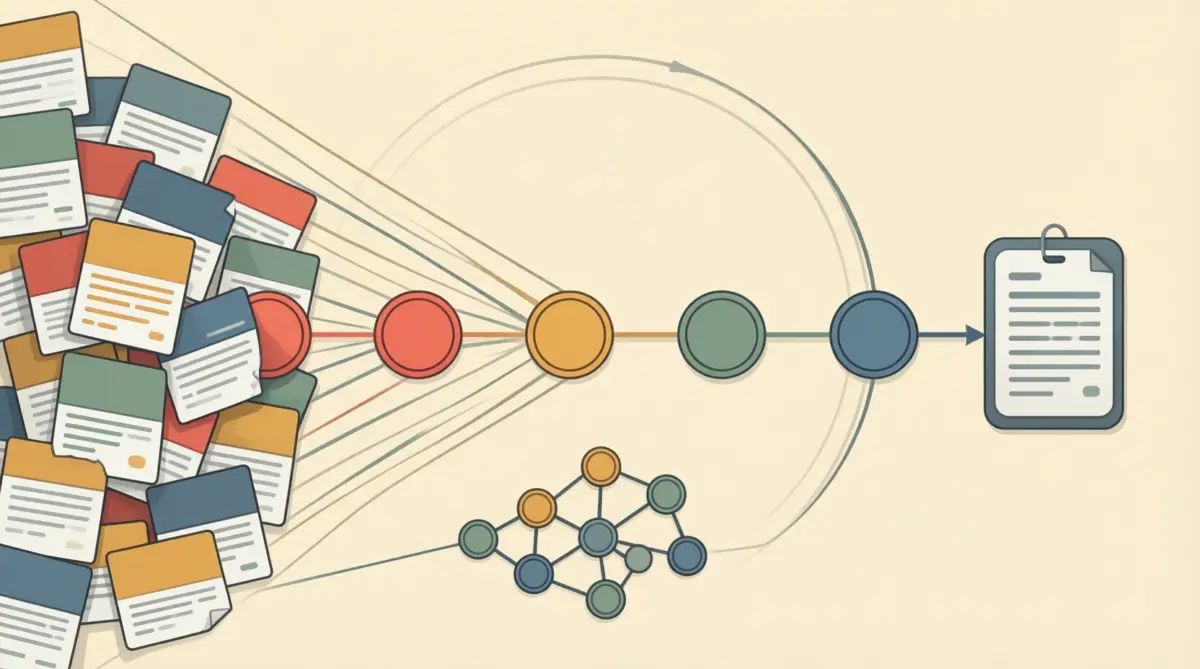
The real reason e-commerce marketing numbers cannot be trusted rarely sits in the attribution model itself. Instead, the root of the problem lies much further down the data stack: customer journeys that are poorly stitched together, touchpoints logged across wildly inconsistent formats, and a massive blind spot where ad exposure never makes it into the data warehouse at all.
When the underlying data layer is fundamentally flawed, the choice of attribution model is nothing more than rearranging deck chairs on the Titanic. Get the data layer right, and the choice of model becomes a minor operational detail. Get it wrong, and no algorithm, machine learning routine, or proprietary dashboard will save the output from being utterly useless.
For data engineers, analytics leads, and modern marketing technologists, solving this crisis requires treating attribution less like a marketing puzzle and more like a core data engineering challenge. This comprehensive guide outlines a practical blueprint for constructing a reliable attribution pipeline from scratch—transforming fragmented data chaos into a single, unassailable source of truth.
Detailed Chronology: Building a Resilient Attribution Pipeline
Rebuilding an e-commerce attribution architecture is not a weekend project; it requires a systematic, chronological progression through six distinct phases. Rushing to model data before completing these foundational steps guarantees systemic bias.
Step 1: Define a "Journey" and Establish the Single Source of Truth
Attribution is the mathematical art of assigning credit for a conversion to the touchpoints that preceded it. Before writing a single line of transformation code, however, an engineering team must establish rigorous definitions for both ends of that relationship.
First, the conversion event must originate directly from your order management system (OMS) or customer relationship management (CRM) database—never from an ad platform pixel. Platforms like Meta, Google, and TikTok are inherently incentivized to over-report their own impact, often resulting in overlapping conversion claims governed by proprietary counting rules. Your internal order table is the only unbiased source of truth that every cross-functional stakeholder can agree upon.
Second, the customer "journey" must be defined as the ordered set of touchpoints belonging to a single, resolved individual within a strictly enforced lookback window. For the vast majority of e-commerce operations, a window spanning 30 to 90 days covers the realistic consumer consideration cycle.
- The Golden Rule: Pick one window and apply it universally. Using fragmented lookback windows—such as a 7-day window for paid social and a 30-day window for search—is one of the quietest, most destructive ways to artificially bias your channel attribution results.
Step 2: Master Identity Resolution Before Counting Anything
A consumer who browses via mobile Safari, clicks a retargeting email on a corporate laptop, and ultimately completes a transaction inside a dedicated mobile app will register as three completely distinct individuals in raw tracking data. Identity resolution—or stitching—is the unglamorous core of modern attribution.
To bridge these fragmented touchpoints, engineering teams must deploy a layered key-matching approach:
- Deterministic Keys: Logged-in user IDs, hashed email addresses, and phone numbers captured during checkout or account creation.
- Probabilistic Keys: Device fingerprints, IP-address-plus-user-agent combinations, and session cookies.
Teams must maintain an identity graph table that systematically records which identifiers belong to a specific customer and when each link was forged. Later in the analytics lifecycle, when a conversion path looks anomalous, the ability to trace the exact lineage of an assembled journey saves days of painful debugging.
Leveraging Data Clean Rooms Across Company Boundaries
While internal identity graphs track what your team can directly observe, measuring advertising effectiveness across walled gardens introduces a profound structural hurdle: connecting ad delivery to final purchases without exchanging raw, unencrypted consumer records.
Data clean rooms have evolved from theoretical panel discussions into proven, widely adopted technologies that enable privacy-preserving collaboration. As Peter Nummerdor, Vice President at Videoamp, notes: "Clean rooms have moved from a topic the industry pontificated about on panels, to a proven and widely adopted technology."
Clean rooms support closed-loop attribution, incrementality testing, media mix modeling (MMM) data feeds, and cross-publisher measurement. However, data teams must treat these use cases as distinct operations. An aggregate measurement result concerning audience overlap must remain strictly siloed from the deterministic links used to assemble an individual’s journey.
When pulling data clean-room results into your internal attribution warehouse, maintain explicit output boundaries. If a clean-room query describes conversion lifts for a specific demographic segment, retain that finding at the aggregate cohort level rather than improperly forcing those conversions down to individual customer rows.
Step 3: Construct a Unified Touchpoint Table
Every single customer interaction—whether a paid ad click, an organic search visit, an affiliate referral, or a promotional email open—must land in a single, centralized table governed by a strictly enforced schema. At a bare minimum, this table should capture:
| Field Name | Data Purpose & Specification |
|---|---|
customer_id |
The fully resolved, unified identity pulled directly from the identity graph. |
timestamp |
Precise event occurrence time recorded universally in Coordinated Universal Time (UTC). |
channel |
A standardized, programmatic channel taxonomy (never raw UTM parameters). |
campaign |
Mapped systematically from source marketing systems. |
touch_type |
Categorical classification: click, impression, site visit, email open, etc. |
cost |
Granular media spend data allocated where available, crucial for subsequent ROAS calculations. |
Taming the Taxonomic Chaos
The channel taxonomy field demands far more architectural attention than it typically receives. Human-entered UTM parameters are notoriously messy; values like facebook, Facebook_Ads, fb-paid, and meta will fracture downstream reporting if left unmanaged.
Relying on endless CASE WHEN statements in SQL queries is an anti-pattern. Instead, engineering teams should maintain a centralized mapping table that automatically normalizes incoming string variations into an approved parent taxonomy before any attribution modeling occurs.
Step 4: Address the Unseen Impressions
This is the precise juncture where the vast majority of in-house attribution builds ultimately stall. Capturing clicks is trivial; capturing impressions from walled gardens like Meta, TikTok, and Snapchat is notoriously difficult because these platforms deliberately withhold user-level exposure data.
Yet, for modern e-commerce brands, paid social advertising functions primarily through brand exposure. Consumers routinely view an ad, absorb the messaging without clicking, and subsequently initiate a direct or branded search query days later. Ignoring these invisible impressions systematically overcredits search and direct traffic—the very channels designed to harvest demand that upper-funnel platforms created in the first place.
Recovering Conversion Signals Without Conflating Them with Impressions
It is vital to distinguish between missing purchase events and missing ad industry impressions, as they require entirely different technical interventions:
- Server-Side Tracking: Industry analyses indicate that standard client-side browser pixels routinely miss 30% to 50% of conversion events due to ad blockers, Intelligent Tracking Prevention (ITP), and privacy regulations. Implementing server-side tracking (via Meta CAPI or server-side Google Tag Manager) utilizing
event_iddeduplication bridges this conversion gap. - Impression Modeling: To account for unobserved ad impressions, data teams must implement either econometric Media Mix Modeling (MMM) to ingest high-level spend data or probabilistic reach-and-frequency allocation models.
Whichever path your organization chooses, modeled touchpoints must be clearly flagged within the database schema. Analysts must always retain the technical capability to cleanly separate observed reality from estimated projections.
Step 5: Select an Explainable Attribution Model
Once a clean, deduplicated, and unified journey table is operational, selecting an attribution model becomes the easiest phase of the project. Organizations typically choose between:
- Rule-Based Models: First-click, last-click, linear, time-decay, or position-based. Highly transparent and easy to explain to non-technical stakeholders, but fundamentally simplistic.
- Algorithmic/Data-Driven Models: Markov chains or Shapley value algorithms that calculate the true marginal probability of conversion added by each touchpoint.
While algorithmic models reflect consumer behavior with far greater fidelity, they are notoriously difficult to explain to a skeptical Chief Marketing Officer. A proven organizational compromise is to run a transparent rule-based model alongside an advanced algorithmic model, investigating discrepancies only where the two systems disagree sharply.
Step 6: Validate Against Empirical Experiments
Attribution models are ultimately sophisticated mathematical estimations; consequently, their outputs must be rigorously validated against independent empirical methods.
Geo-experimental holdout tests, conversion lift studies, and planned budget pauses produce causal reads for individual channels. If an algorithmic attribution model claims that paid social drives 60% of total enterprise revenue, but a strict regional holdout test demonstrates virtually zero drop in sales when paid social spend is entirely switched off, the attribution model requires radical recalibration—not defense.
Data teams should execute at least one rigorous validation test per quarter on their largest marketing channel. Over time, tracking the delta between modeled attribution and measured incrementality serves as the ultimate health metric for your entire data stack.
Supporting Context & Metrics: The Cost of Bad Data
The financial and operational implications of broken attribution architectures cannot be overstated. When marketing executives make budget allocation decisions based on un-reconciled platform dashboards, enterprise capital is routinely incinerated.
Consider the cross-platform claim discrepancy: Meta, Google, and TikTok routinely report conversion numbers that, when added together, exceed actual audited business revenue by 200% to 300%. Industry benchmarks consistently show ad platforms reporting upwards of 1,200 total conversions while underlying enterprise platforms (such as Shopify Plus or custom ERPs) record only 650 actual orders.
[Ad Platform Dashboards] ---> Overlapping Claims (e.g., 1,200 Conversions)
[Internal OMS / Shopify] ---> Actual Validated Orders (e.g., 650 Sales)
[Data Warehouse Layer]   ---> Reconciled, Deduplicated Attribution Pipeline
When data teams fail to reconcile these figures in a centralized warehouse, leadership teams inherit a distorted reality. Budget is funneled toward channels that merely claim credit for transactions that would have occurred organically, starving upper-funnel growth engines of necessary capital.
Official Statements and Industry Insights
As the e-commerce landscape matures into a privacy-first ecosystem, industry leaders are increasingly vocal about the necessity of robust data layers over flashy attribution algorithms.
Addressing the evolution of cross-platform measurement, Peter Nummerdor of Videoamp emphasizes the practical reality of modern data infrastructure:
"Clean rooms have moved from a topic the industry pontificated about on panels, to a proven and widely adopted technology."
This shift underscores a broader industry realization: external data collaboration can no longer rely on loose, ad-hoc file sharing. It demands structured, privacy-compliant architectures embedded directly into the modern data stack.
Similarly, technical analyses from marketing infrastructure providers highlight the widening gulf between client-side tracking failures and server-side capture reliability. Reports from digital engineering firms indicate that traditional browser pixels now fail to capture nearly half of all consumer conversion events, making server-side API integrations an absolute prerequisite for any credible attribution pipeline.
Future Outlook: The Autonomous Data-Driven Enterprise
Looking ahead to the remainder of the decade, the trajectory of e-commerce attribution points away from isolated marketing analytics and toward fully integrated enterprise data engineering.
As browser privacy restrictions tighten, third-party cookies vanish entirely, and regulatory frameworks become increasingly stringent, heuristic attribution models will become entirely obsolete. Forward-thinking e-commerce brands are already shifting investments away from black-box platform dashboards and toward proprietary, warehouse-native attribution pipelines.
In this future state, data engineers and analysts will no longer spend their days arguing with CMOs over conflicting channel ROAS figures. By getting the foundational data layer right—stitching identities with precision, normalizing taxonomies, capturing server-side events, and continuously validating outputs against empirical holdout experiments—data teams can finally put the attribution debate to rest, letting clean, verifiable data speak for itself.