Executive Overview
In the modern corporate ecosystem, few hiring errors are as pervasive—or as quietly destructive—as treating software engineers and data analysts as interchangeable technical talent. Job descriptions routinely blur the lines between these two disciplines, tossing overlapping programming languages, database queries, and analytics tools into a single, generic posting as if any technical professional could seamlessly slide into either seat.
This conflation is more than an HR inconvenience; it is a fundamental misalignment of organizational capability. At its core, a hiring decision must turn on the nature of the work itself. When an enterprise needs reliable, scalable infrastructure that can withstand high-throughput production environments, it requires a software engineer. When leadership needs rigorous, evidence-based insights to navigate complex business questions, it requires a data analyst.
Treating these roles as synonyms creates immediate operational friction. An analyst tasked with producing strategic business intelligence may find themselves drowning in pipeline maintenance and broken API integrations. Conversely, a software engineer hired to build resilient data architecture may struggle to translate raw metrics into actionable market strategies. By examining the distinct training, daily habits of mind, and core methodologies of both disciplines, organizations can build technical teams that are properly equipped for the challenges they face.
Detailed Chronology: The Evolution and Divergence of Technical Roles
To understand how organizations routinely misallocate technical talent, it is helpful to trace how software engineering and data analytics evolved from adjacent IT support functions into distinct, highly specialized professional pillars.
Phase One: The Era of Generalist IT (Early 2000s and Prior)
In the early days of corporate computing, the boundary between writing code and analyzing data was porous. Businesses typically employed generalist IT professionals or database administrators (DBAs) who built the software, managed the database schema, wrote the SQL queries, and generated the monthly executive reports. Because data volumes were manageable and software ecosystems were less complex, a single technical resource could reasonably span the entire lifecycle of a digital asset—from writing the initial script to pulling the final CSV export.
Phase Two: The Big Data Explosion (2010–2020)
As digital transformation accelerated, organizations began accumulating unprecedented volumes of data. This era saw the birth of modern "Big Data," characterized by distributed computing frameworks like Hadoop, cloud-native storage solutions, and real-time streaming architectures.
During this period, software engineering fractured into specialized sub-disciplines: backend engineering, DevOps, platform engineering, and site reliability engineering (SRE). Simultaneously, data analysis evolved beyond simple business reporting into advanced business intelligence, predictive modeling, and data science. Despite this divergence, HR departments and hiring managers often failed to update their mental models, continuing to treat "technical talent" as a monolith.
Phase Three: The Contemporary Talent Mismatch (Present Day)
Today, organizations operate in hyper-competitive markets where milliseconds of system downtime cost millions of dollars, and flawed business data leads to disastrous strategic pivots. Yet, job postings continue to list "SQL, Python, and cloud platforms" as generic requirements for both engineering and analytical seats.
When a company hires an analyst expecting them to architect fault-tolerant data pipelines, or hires an engineer expecting them to conduct nuanced qualitative analysis on customer churn, the mismatch inevitably surfaces—usually only after a costly recruitment process and months of operational friction.
Supporting Context & Metrics: The Anatomy of Two Distinct Disciplines
A surface-level tool overlap—such as the use of Python or SQL—often masks profound differences in daily objectives, educational pathways, and professional mindsets.
What Kind of Problems Data Analysts Are Trained to Solve
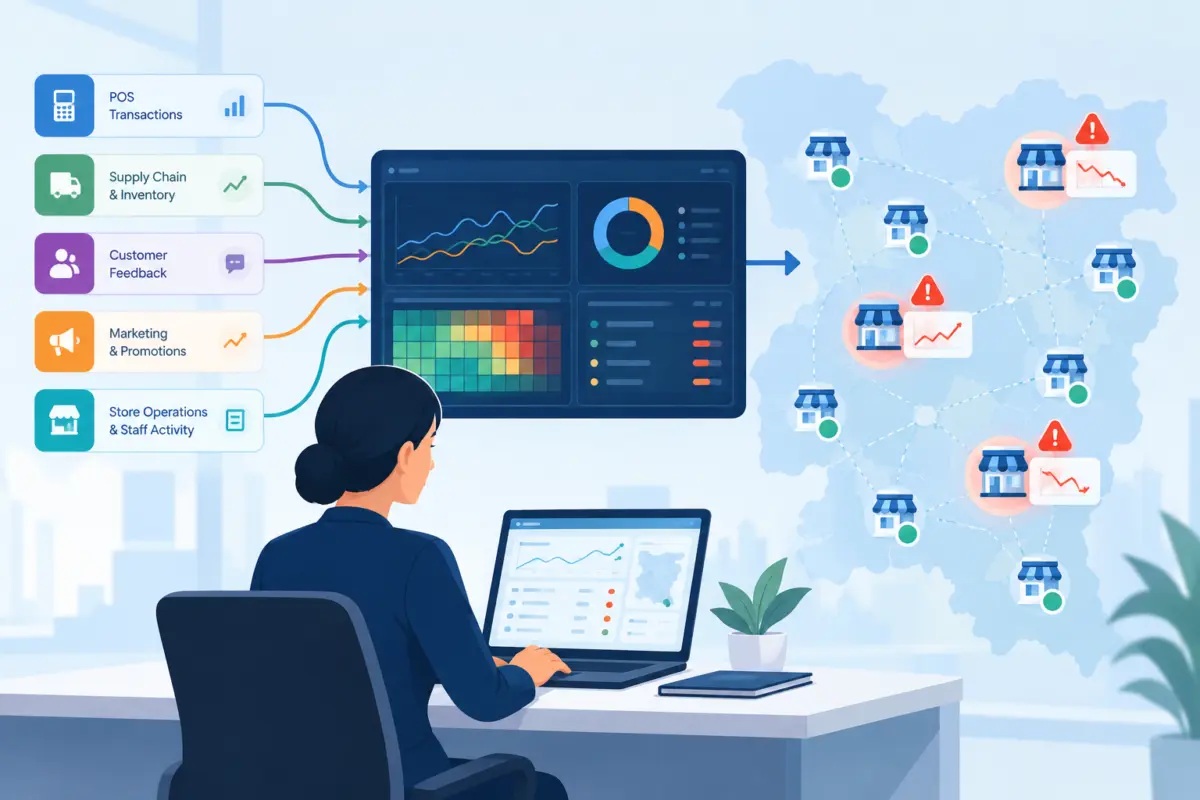
Data analysts approach problems through an investigative lens. Their work begins with data that already exists within an enterprise ecosystem. Rather than building new systems to generate data, analysts explore existing repositories to identify patterns, trends, and causal relationships that inform high-stakes business decisions.
Anyone weighing these two career paths—or designing organizational development programs—must understand that these disciplines require genuinely different daily habits of mind. An analyst’s investigation always starts with a business question. They ask: What does the underlying data reveal about this specific hypothesis? From there, they follow the evidence wherever it leads, applying statistical reasoning to separate signal from noise.
However, raw statistical literacy is insufficient on its own. The true value of a data analyst lies in their ability to translate complex numerical findings into clear, actionable recommendations for non-technical stakeholders.
What Kind of Problems Software Engineers Are Trained to Solve
In stark contrast, software engineers approach problems through a constructive lens. They design, build, and maintain the complex digital infrastructure that collects, processes, and stores data in the first place. Their work exists upstream of the data an analyst later explores.
An engineer starts from a technical requirement and builds a reliable, scalable system designed to meet strict performance parameters under real-world conditions. Success in this field depends entirely on engineering rigor, sound system design, and defensive programming.
To illustrate the stakes of software engineering failure, one need only look at infrastructure reliability reports. For instance, a June 12, 2025 incident report published by Cloudflare documented a severe storage failure that caused 90.22% of requests to their Workers KV global key-value storage service to fail. While cached data remained accessible, any request requiring a round-trip to the underlying storage layer collapsed. Mitigating and preventing such cascading architectural failures is the domain of the software engineer—not the data analyst.
Official Statements and Industry Frameworks
Leading professional bodies and labor authorities explicitly separate these disciplines, underscoring that their underlying methodologies, training standards, and career trajectories belong to distinct professional universes.
The INFORMS Analytics Framework
The Institute for Operations Research and the Management Sciences (INFORMS) places business problem framing at the absolute forefront of its professional analytics framework. INFORMS emphasizes rigor not merely in how data is collected or stored, but in how it is interpreted and applied to organizational strategy. Data analysts are trained to frame unstructured business problems into quantifiable analytical challenges, bridging the gap between raw data and executive decision-making.
The IEEE Computer Society’s SWEBOK Guide
Conversely, the IEEE Computer Society—in its authoritative Guide to the Software Engineering Body of Knowledge (SWEBOK Guide)—codifies software design, construction, testing, maintenance, and configuration management as the core pillars of engineering discipline. SWEBOK treats structural integrity, concurrency management, and operational resilience as central to producing software that can survive unpredictable operating conditions.
Bureau of Labor Statistics (BLS) Projections
Labor data further highlights the divergence of these paths. The U.S. Bureau of Labor Statistics (BLS) tracks data scientists and analytics professionals separately from software developers. In its labor projections, the BLS anticipates robust, specialized growth across both sectors—reflecting the distinct and expanding demands for system builders versus analytical investigators. However, industry analysts caution that data scientists are not interchangeable with business data analysts, just as neither can substitute for a systems engineer.
Why Organizations Conflate These Skill Sets
The persistence of the hybrid "unicorn" job description—seeking a professional who can architect cloud databases, build microservices, write React frontends, and deliver executive-ready Tableau dashboards—stems from several systemic misconceptions:
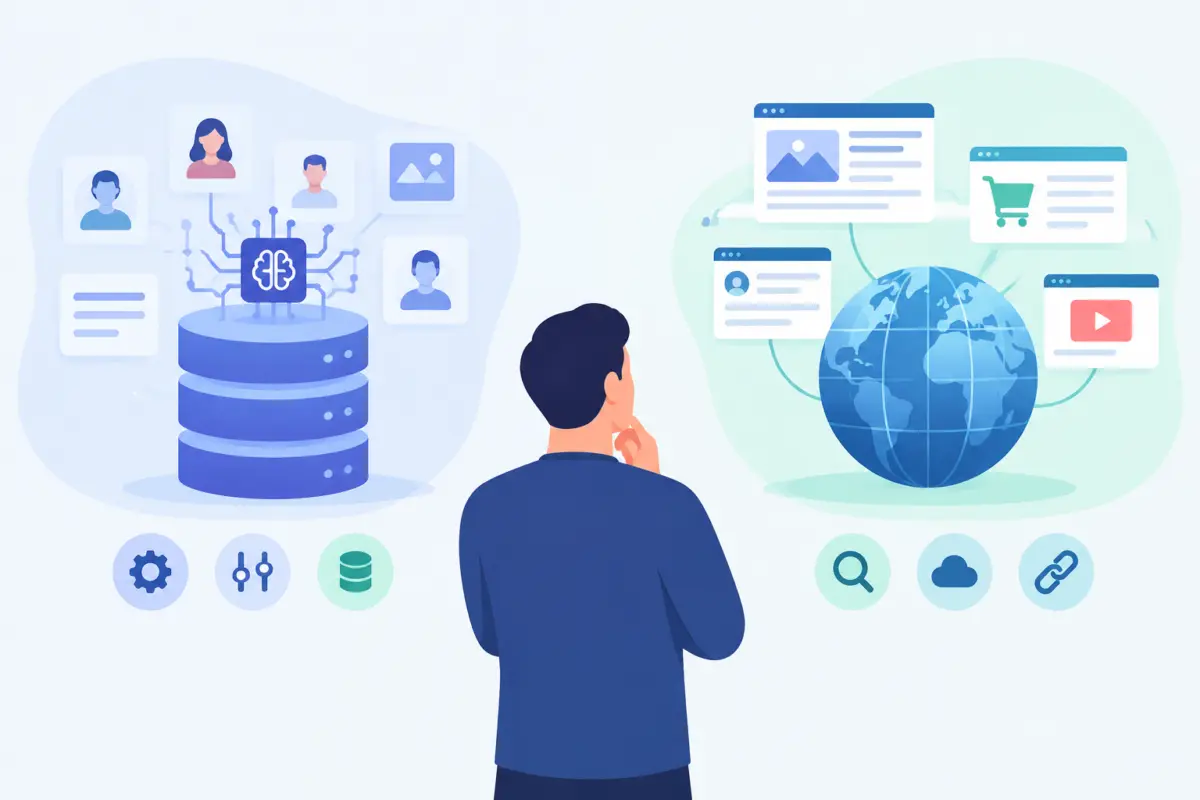
- Tool Overlap: Both software engineers and data analysts rely heavily on programming languages like Python and R, query languages like SQL, and cloud storage environments like Snowflake or AWS S3. This surface-level technical crossover tricks non-technical recruiters into assuming the underlying cognitive skill sets are identical.
- The "Data" Umbrella: Because both roles deal with data, organizations frequently lump them into generic "Data and Tech" departments without establishing clear sub-specialties.
- Misaligned Responsibilities: When organizations conflate these roles, employees are thrust into impossible positions. An analyst hired to build strategic forecasting models may suddenly find themselves responsible for restarting failed data extraction pipelines and debugging race conditions in a production database. Conversely, a software engineer may find their time diverted from building core product infrastructure to answering ad-hoc requests for marketing dashboards.
The ultimate cost of this mismatch is profound: dashboards may display numbers that no one trusts, while core application infrastructure degrades due to a lack of dedicated engineering oversight.
Future Outlook: Building Effective Technical Teams
As artificial intelligence and automated tooling continue to reshape the technology landscape, the distinction between software engineering and data analytics will only become more pronounced. While AI tools can automate routine code generation and basic data queries, they cannot replace the domain expertise required to frame a complex business problem or architect a fault-tolerant distributed system.
Organizations that wish to remain competitive must adopt a more disciplined approach to team composition:
- Upfront Clarity in Job Descriptions: Before drafting a technical job posting, hiring managers must audit the core problem they need solved. If the primary bottleneck is data interpretation and strategic insight, write an analyst job description. If the bottleneck is system throughput, uptime, or data ingestion pipelines, write an engineering job description.
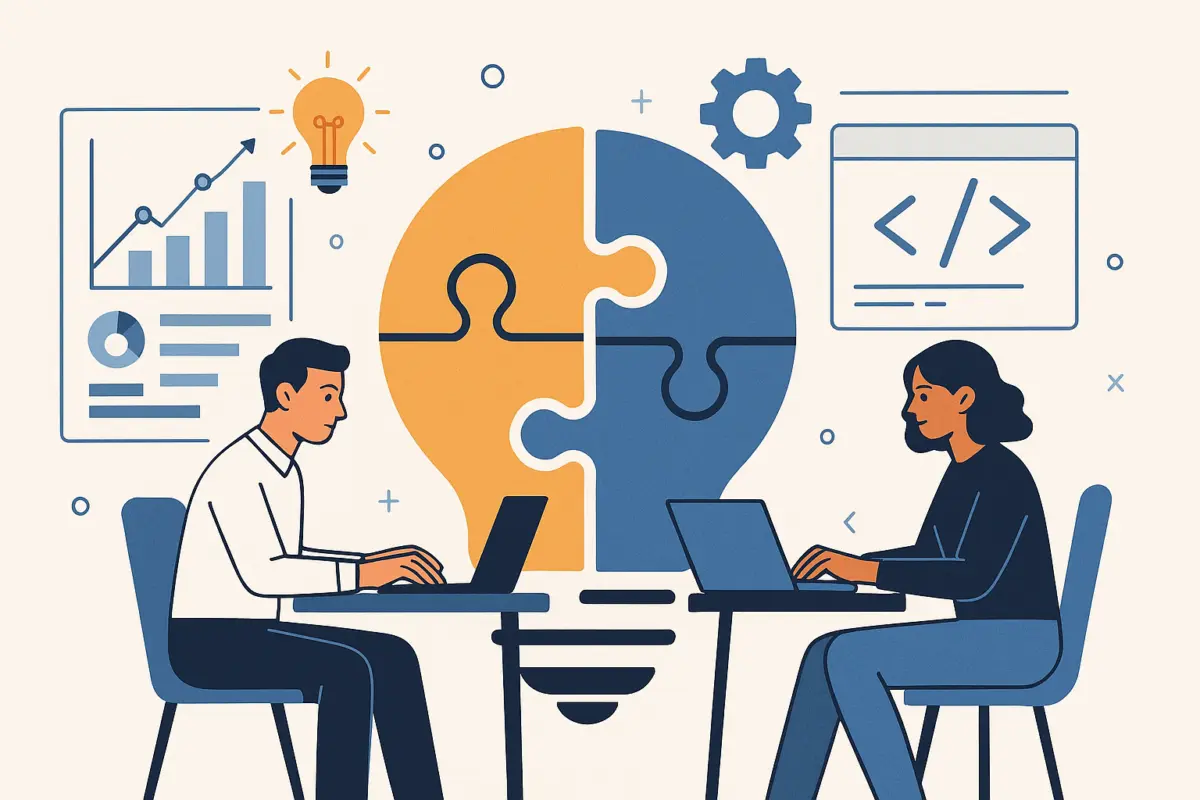
- Encouraging Close Collaboration: Rather than seeking a single unicorn candidate, organizations should cultivate distinct functions for engineering and analytics, encouraging them to collaborate closely. Engineers should build the robust data platforms that analysts rely on, while analysts provide feedback on data quality and schema usability.
- Targeted Interview Work Samples: During the interview process, ditch generic technical tests in favor of work samples that expose actual responsibilities. For an analyst candidate, ask them to explain how missing records or selection bias could invalidate a critical business recommendation. For an engineering candidate, present a scenario where a core storage dependency fails, and evaluate how their system architecture handles the fallout.
By respecting the profound differences between building reliable software and extracting rigorous business evidence, organizations can eliminate costly hiring mismatches and build technical teams capable of thriving in an increasingly data-driven world.