Executive Overview
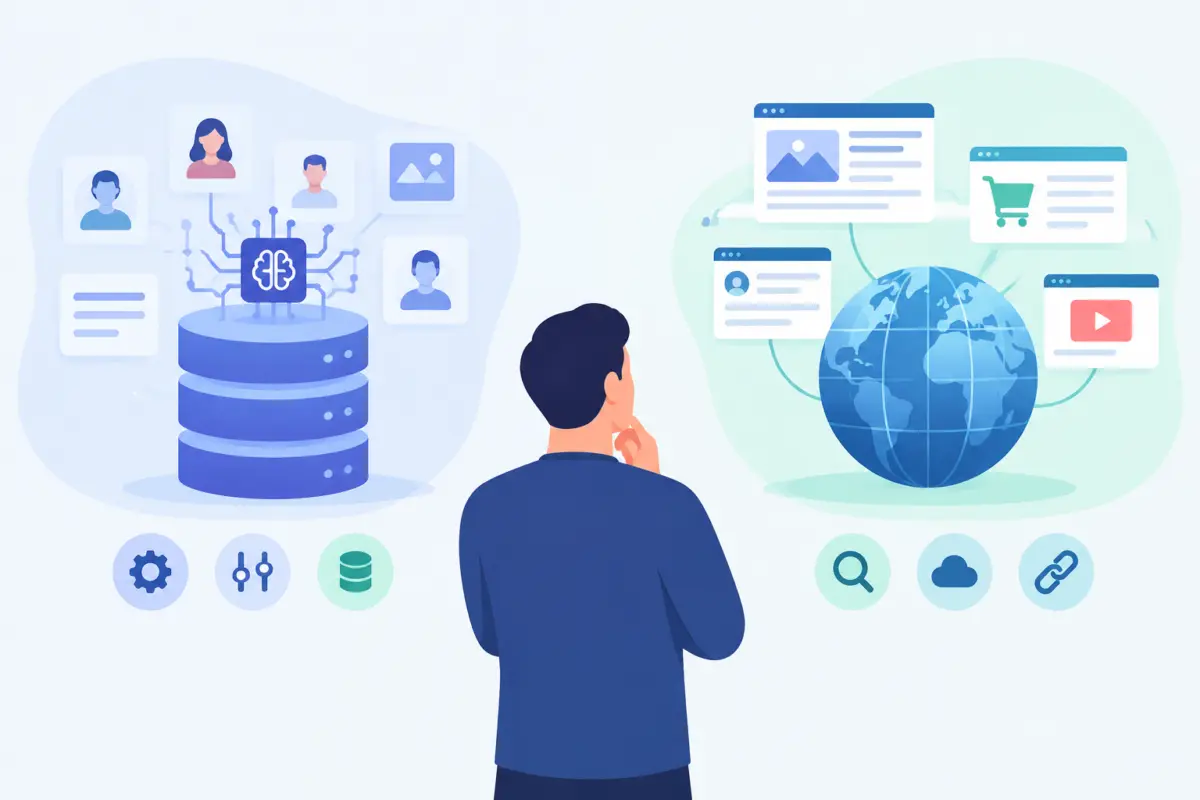
As artificial intelligence systems transition from experimental sandboxes to mission-critical enterprise infrastructure, machine learning (ML) engineering teams face a foundational architectural dilemma: the choice of data. For years, the prevailing wisdom treated training inputs as a monolithic resource—a pool of records fed into algorithms regardless of origin. Today, however, the industry is witnessing a structural decoupling of data sources into two distinct paradigms: real-world web data and synthetic data generation.
Synthetic data offers an on-demand, scalable sandbox. It allows engineering teams to stress-test predictive models, simulate extreme edge conditions, and bypass the prohibitive manual labor and financial costs of labeling millions of raw data points. Yet, artificial records inherently lack ground truth. Without empirical anchors grounded in real-world user behavior, volatile market shifts, and messy, unpredictable edge cases, predictive models experience rapid drift, diverging catastrophically from operational reality.
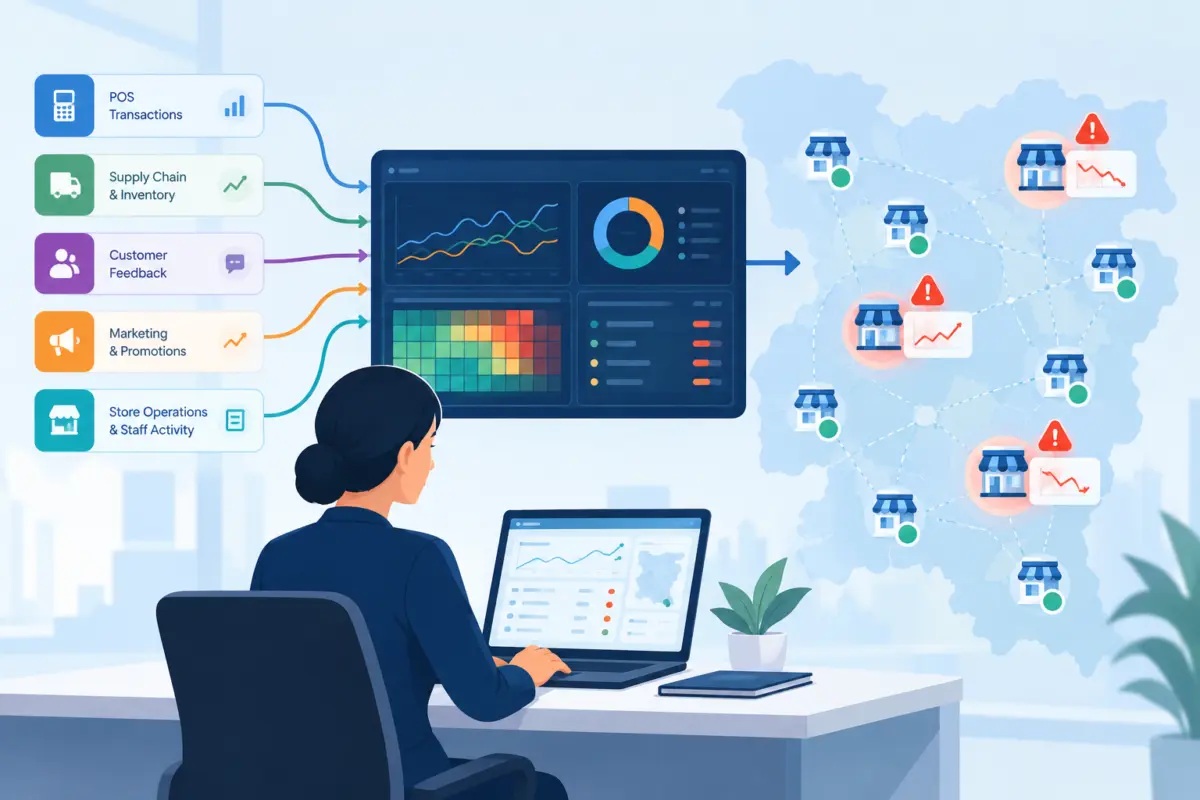
Conversely, real web data documents observable events. It records what actually happened, where, and when—tracking live e-commerce price adjustments, sudden corporate hiring surges, and shifting macroeconomic consumer sentiment in real time. However, relying solely on historical web data leaves pipelines vulnerable to sparse tail events, data scarcity, and regulatory collection hurdles.
The industry consensus among high-performing ML teams points toward an integrated approach. Real web data anchors baseline operational reality, while synthetic data scales training distributions and simulates high-risk edge cases. As public internet spaces become increasingly saturated with AI-generated content, the primary bottleneck in big data engineering is no longer raw volume, but verified provenance. Organizations that master the closed feedback loop—detecting real-world shifts via live web feeds, generating targeted synthetic corner cases, and validating models against unmanipulated inputs—will capture the definitive competitive advantage in enterprise AI.
Detailed Chronology: The Evolution of Data Strategies in ML
To understand the current tension between synthetic and real-world data, it is necessary to examine the chronological progression of data acquisition strategies over the past decade.
Phase 1: The Era of Unfiltered Web Scraping (2010–2018)
In the early days of deep learning, the prevailing strategy was volume-driven. Engineering teams scraped vast swathes of the public internet, ingesting unstructured HTML, user forums, and public registries. Data cleaning was primitive, and models were trusted to extract patterns from raw, uncurated corpora. While this approach powered early breakthroughs in natural language processing and computer vision, it suffered from severe noise, bias, and a lack of data lineage.
Phase 2: The Annotation and Labeling Bottleneck (2018–2022)
As models scaled in parameter size, the demand for clean, annotated data outpaced the supply of raw web pages. Enterprises invested heavily in human-in-the-loop annotation pipelines, third-party labeling services, and internal data ops teams. This era introduced steep financial and temporal friction; preparing a dataset for production deployment often took months, delaying time-to-market for critical enterprise applications.
Phase 3: The Rise of Generative Simulation (2022–2024)
Faced with labeling fatigue and privacy regulations governing user data, the AI industry turned aggressively toward synthetic data generation. Leveraging large language models (LLMs) and advanced statistical simulators, teams began manufacturing millions of artificial records to train downstream models. This era unlocked rapid prototyping and cost-effective stress-testing, but it also sowed the seeds for latent structural vulnerabilities, including metric illusion and model collapse.
Phase 4: The Closed-Loop Integration Paradigm (2024–Present)
The contemporary era is defined by synthesis rather than substitution. Recognizing the fatal flaws of pure synthetic diets—exemplified by landmark academic warnings regarding model degradation—leading organizations have abandoned the notion that synthetic and real data are interchangeable. Modern architectures implement automated feedback loops where real-world web signals dictate the parameters of synthetic generation, ensuring that simulated edge cases remain tethered to actual operational dynamics.
Supporting Context & Metrics: Navigating the Production Pipeline
When designing production-grade data pipelines, engineering teams must evaluate synthetic and real web data across operational timelines, risk profiles, and collection mechanisms.
Operational Timelines and Distortions
A fundamental divergence between the two data types lies in their temporal mechanics:
- Real Web Records: Carry a concrete observation timestamp documenting a verifiable event in the physical or digital world.
- Synthetic Records: Carry a generation timestamp, but their statistical distribution depends entirely on the source training sample. If that baseline dataset is stale—even by six months—generating ten million new rows today merely magnifies yesterday’s market anomalies.
The Anatomy of Synthetic Risk
Synthetic training data introduces three distinct operational hazards that standard lab benchmarks frequently fail to capture:
- Metric Illusion: When a model trains and evaluates on data from the same generative source, it learns the internal mathematical artifacts of the generator rather than genuine market mechanics. High accuracy scores in these environments reflect algorithmic compatibility, not production readiness.
- Event Frequency Distortion: While generating thousands of rare fraud or inventory stockout examples helps an algorithm recognize anomalous signatures, it artificially skews the base rate. In production, this distortion triggers a surge of false positives and wasted manual reviews. Synthetic data shows what an anomaly looks like, but it cannot establish how often it occurs.
- Unverified Causality: A synthetic table might suggest that lowering a product price by 10% increases sales by 30%. That correlation may simply echo unmodeled holiday promotions or supply chain artifacts present in the seed data. Acting on unverified assumptions in a dynamic market turns statistical noise into an expensive pricing blunder.
Channels for Real Web Data Collection
Collecting verified, production-grade real web data requires selecting from four primary acquisition channels based on latency needs, governance standards, and engineering capacity:
[Public Repositories] ----> Initial Benchmarking & Baseline Indicators
[Commercial Datasets] ----> Rapid Prototyping & Historical Archives
[Direct APIs]         ----> Structured JSON/Parquet Feeds (Rate-Limited)
[Custom Scrapers] ----> Complete Control, Headless Browsers, Proxies- Public Repositories: Platforms such as data.gov and Eurostat offer free access to official registries, economic indicators, and academic baselines. While convenient for initial benchmarking, teams must scrutinize license terms, field completeness, and refresh cadences.
- Commercial Datasets: Third-party vendors sell packaged point-in-time snapshots and historical archives via recurring feeds. This allows engineering teams to deploy prototypes rapidly, though teams sacrifice control over underlying schemas and collection windows.
- Direct APIs: Deliver structured JSON or Parquet feeds without the overhead of parsing raw HTML. While reliable, enterprise rate limits and payload quotas can restrict ingestion velocity, and upstream endpoint changes can break downstream feature pipelines without warning.
- Automated Custom Web Scrapers: Building automated pipelines using headless browser frameworks (e.g., Playwright) or distributed extractors (e.g., Scrapy) provides complete control over intake. Specialized tooling handles operational roadblocks such as bot challenges, IP rate limiting, and dynamic JavaScript rendering. Alternatively, managed scraping partners handle proxy rotation and schema drift, delivering clean records directly into enterprise data warehouses.
Official Statements and Industry Insights
The divergence between synthetic simulations and empirical ground truth has prompted significant commentary from the scientific and enterprise research communities.
Addressing the mathematical degradation inherent in recursive synthetic training, Dr. Ilia Shumailov and his research colleagues published a landmark study in Nature (July 2024), demonstrating the mechanics of model collapse:
"Training generative models recursively on model-produced content triggers model collapse. Over successive generations, statistical tail events vanish and the model’s output degenerates into repetitive, low-variance noise. When AI is fed on its own digital echoes, the tail wags the dog—rare, vital insights are smoothed out of existence, leaving behind a sterile average."
This empirical finding underscores the irreplaceable nature of real-world observations. Without fresh injections of organic data, generative models inevitably consume their own intellectual capital.
On the enterprise risk side, global research and advisory firm Gartner released findings from an enterprise data management study emphasizing the strict prerequisite of data quality in AI deployments:
"Organizations will abandon 60% of AI projects unsupported by AI-ready data through 2026. Clean, audited source data is a hard prerequisite for reliable machine learning. Treating synthetic simulations as empirical ground truth without rigorous validation against live operational flows introduces unquantifiable enterprise liability."
These statements highlight a unified industry reality: synthetic data is a powerful analytical scalpel, but it cannot serve as the nutritional foundation for intelligent systems.
Future Outlook: The Architecture of Resilient AI Systems
Looking toward the horizon of enterprise artificial intelligence, the debate will no longer center on whether to choose real web data or synthetic data. The organizations that achieve sustained competitive advantage will be those that construct agile, automated feedback loops uniting both domains.
Future data pipelines will operate on a continuous tripartite cycle:
- Detection: Live web ingestion engines continuously monitor the wild, capturing real-world shifts in consumer sentiment, pricing dynamics, and competitor behavior to establish empirical ground truth.
- Simulation: Engineering teams utilize that fresh signal for targeted data augmentation, manufacturing synthetic corner cases, stress-testing rare failure modes, and balancing sparse classification classes safely off-line.
- Validation: Retrained models undergo rigorous automated validation against unmanipulated, real-world inputs to verify production readiness before deployment.
Furthermore, as synthetic content proliferates across the public internet, verified provenance will become the most valuable currency in big data engineering. Organizations that invest in sophisticated data governance, robust scraping infrastructure, and disciplined synthetic curation will avoid the pitfalls of metric illusion and model collapse. By respecting the distinct functional roles of real observations and artificial simulations, enterprise engineering teams can build resilient, self-correcting machine learning systems capable of thriving in an unpredictable operational world.