Executive Overview
For most mid-market enterprises, their current data infrastructure was never a deliberate architectural creation. Rather, it is a mosaic of expediency—an evolutionary artifact of deadlines met, localized reporting gaps patched, and departmental software choices made in silos. A connector added to resolve a sudden reporting bottleneck here; a reporting tool adopted because a newly hired analytics lead was familiar with its interface there; a cloud data warehouse spun up under immense timeline pressure. Individually, each decision made pragmatic, tactical sense. Together, they have forged a sprawling, fragile data stack that few individuals across the organization fully comprehend.
Today, this accidental complexity is manifesting in the business metrics that leadership cares about most. Beneath the surface of dashboard refreshes and weekly executive summaries, architectural fragmentation quietly undermines data quality and governance, rendering consistent policy enforcement across disconnected systems nearly impossible. Discrepancies between departmental reports are no longer minor anomalies; they are symptoms of a systemic failure in trust.
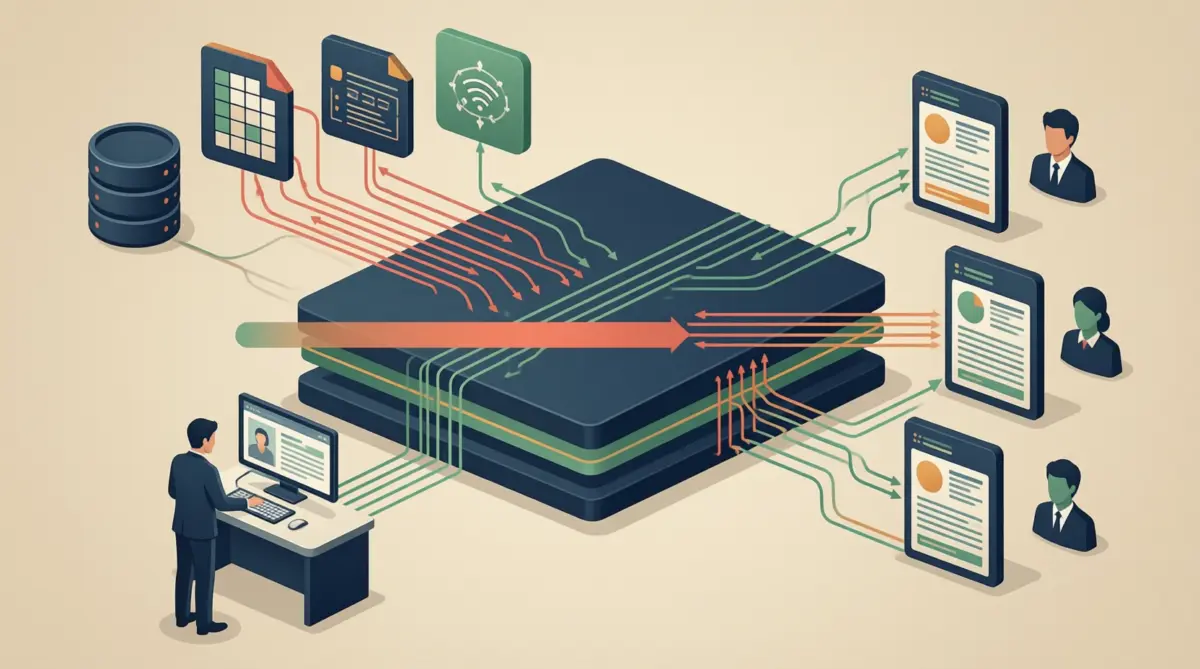
As organizations scale past the threshold where manual oversight and duct-tape integrations are viable, data stack consolidation has emerged as a critical strategic imperative. By bringing connection, data transformation, business intelligence reporting, and compliance policy enforcement into a single, unified managed environment, enterprises can eliminate the friction that stalls operations. However, migration is not a universal panacea. For mid-market teams, the decision to consolidate hinges on the frequency of recurring reporting discrepancies, the fragility of data handoffs, and operational dependence on individual staff members. Where those friction points are isolated, rigorous documentation and targeted quality checks may suffice. But for organizations buckling under the weight of their own tools, the shift toward a unified data management platform represents the difference between reactive firefighting and proactive, data-driven execution.
Detailed Chronology: The Anatomy of an Accidental Architecture
To understand how mid-market companies arrive at a state of architectural paralysis, one must examine the typical lifecycle of data tooling growth—a trajectory defined by incremental accumulation and deferred technical debt.
Phase 1: The Scrambled Inception (Early Stage to Rapid Growth)
In the formative stages of a mid-market company, data infrastructure is non-existent or rudimentary. Teams rely on native application exports—pulling CSV files from Salesforce, Stripe, and QuickBooks—and stitching them together in local spreadsheets. As transaction volumes swell, this manual labor becomes unsustainable. Under pressure from leadership to provide real-time visibility, an operations manager or early data analyst deploys a quick-fix ETL connector to pipe raw data into a newly provisioned cloud data warehouse. It works. A reporting gap is closed.
Phase 2: Decentralized Procurement and the Silo Effect
As the enterprise expands horizontally, different business units begin procuring their own tooling without cross-departmental coordination. The marketing department adopts a specialized attribution platform because its vendor promised rapid deployment. Finance, relying on legacy enterprise resource planning (ERP) systems, demands strict SQL-based access controls and rejects the marketing tool’s data schema. To bridge the divide, a custom Python script is written by a resourceful developer to sync data between the two platforms.
[SaaS Apps: Salesforce, Stripe]
       │
       ▼  (Ad-hoc ETL Connector)
[Cloud Warehouse] ──(Custom Python Script)──> [Finance ERP]
       │
       ▼  (Departmental BI Tool)
[Marketing / Sales Dashboards] ──> [Conflicting Executive Reports]
Phase 3: The Maintenance Tipping Point
Over time, personnel churn takes its toll. The developer who wrote the custom Python syncing script leaves the company, taking the institutional knowledge of that specific data pipeline with them. When an upstream API changes at the SaaS provider level, the script breaks silently.
By this stage, the organization operates an assembled stack comprising four or five discrete point solutions. No single owner oversees the end-to-end data flow. Accountability for data anomalies becomes diffuse, finger-pointing between departments becomes routine, and executive meetings frequently devolve into debates over whose report is mathematically "correct" rather than strategic discussions about what the insights actually mean.
Supporting Context & Metrics: The Hidden Costs of Fragmentation
The true expense of an assembled data stack rarely appears as a discrete line item on an invoice. Instead, it is paid in organizational drag, lost decision velocity, and eroded trust.
The Mathematics of Discrepancy
When data tools are selected independently, the gaps between them become human burdens. A marketing analyst pulling campaign ROI from one analytics platform arrives at a different customer acquisition cost than the finance lead querying billing records from the ledger system. When these two metrics collide in a Monday morning leadership meeting, the ensuing debate halts strategic momentum.
These discrepancies represent fundamental data quality failures that erode trust across the entire reporting pipeline. According to industry benchmarks regarding data reliability, mid-market organizations lose an estimated 12% to 15% of staff productivity solely to data reconciliation tasks—hours spent manually cross-referencing mismatched spreadsheets rather than executing core business initiatives.
The Fragility of Tribal Knowledge
The maintenance burden scales non-linearly with every additional connector and custom script. Every point of integration represents a potential point of failure. When teams attempt to introduce new capabilities—such as feeding structured historical data into machine learning pipelines or launching a customer-facing analytics portal—they frequently discover that 80% of their data engineering capacity is consumed entirely by "keeping the lights on."
Governance suffers in parallel. When no centralized authority oversees the data lifecycle, policy enforcement becomes ad-hoc. Compliance vulnerabilities multiply, access controls drift, and the enterprise finds itself exposed to regulatory risks simply because data provenance cannot be definitively audited.
Official Industry Perspectives and Expert Insights
As enterprise data architectures evolve to meet the demands of modern algorithmic workloads, industry thought leaders emphasize that tooling consolidation is inextricably linked to robust governance frameworks.
The Enterprise Data Management Landscape
Evaluating the suitability of unified platforms for mid-market segments requires looking closely at how organizations consume insights. In its comprehensive analysis of enterprise data management tooling, including evaluations of platforms like FineBI, analytics consultancy Improvado identifies mid-market companies—specifically those employing between 100 and 1,000 employees—as prime candidates for business-user reporting frameworks that bypass IT bottlenecks.
This model is especially vital when regional offices or semi-autonomous business units require decentralized operational freedom paired with centralized governance. The acid test for an organization is deceptively simple: Can a non-technical business user produce an accurate, compliant report under shared enterprise rules without waiting for an IT queue to clear? Employee headcount alone is a poor proxy for architectural readiness; operational dependency is the true metric.
Governance in the Age of Autonomous Workloads
The necessity of unified platforms extends far beyond human-centric reporting. As artificial intelligence and autonomous agents are embedded deeper into business workflows, the demands placed on underlying data architectures have fundamentally shifted.
Addressing the changing operational requirements of data lifecycle management in the era of automated systems, Nick Magnuson, Head of AI at Qlik, highlighted the structural evolution required of modern data teams during an industry panel discussion (as reported by SiliconANGLE, April 2026):
"How we think about constructing data and supporting that data through that life cycle now, because we’ve got autonomous things in the mix that aren’t human in nature…"
Magnuson’s observation underscores a critical reality for mid-market enterprises: legacy, fragmented stacks that rely on human intuition to patch broken data handoffs cannot support autonomous agents. When AI workloads consume upstream data, silent pipeline failures do not merely result in a bad spreadsheet—they trigger automated downstream decisions based on corrupted inputs, compounding errors at machine speed.
Strategic Evaluation: When Migration Is Worth It (and When It Isn’t)
Consolidation is not a universal prescription. For some organizations, a full platform migration represents unnecessary disruption; for others, it is an existential operational necessity.
The Diagnostic Framework
Before committing capital and engineering bandwidth to a platform consolidation initiative, leadership teams must honestly appraise their operational environment through three diagnostic questions:
- How many distinct data sources are genuinely active within the environment?
If an organization pulls data from only two or three core systems, an assembled stack may still function reliably. At this small scale, manual data quality checks and lightweight documentation remain manageable without a disruptive platform overhaul. - Where does institutional knowledge reside?
If understanding the entire data flow depends entirely on the memory of one or two key employees, the organization faces a severe single-point-of-failure risk. This risk impacts governance directly; when knowledge is concentrated informally, policy enforcement relies on individuals rather than enforceable system architecture. - Are reporting delays actively damaging business decisions, or merely causing operational frustration?
If delays rarely alter strategic outcomes, the immediate business case for migration is weak. Similarly, if data quality issues are sporadic and easily traced, the governance argument for consolidation loses urgency.
| Approach | Best Fit Scenario | Quality & Governance Execution | Main Limitation |
|---|---|---|---|
| Retain Assembled Stack | Few data sources, rare errors, manageable reporting delays. | Keep ownership boundaries and manual checks explicit. | Ongoing connector maintenance and tool fragmentation remain. |
| Document Existing Stack | Knowledge concentrated in a few key individuals. | Record dependencies, validation rules, and designated owners. | Documentation does not eliminate fragile, error-prone handoffs. |
| Repair Specific Quality Checks | Errors are limited, isolated, and easily traced. | Correct the validation rules behind recurring discrepancies. | Separate reporting tools still require persistent manual harmonization. |
| Consolidate into Unified Platform | Repeated discrepancies, severe delays, mounting maintenance pressure. | Apply shared rules and unified ownership across connection, transformation, and reporting. | Migration effort and unsupported legacy connections can temporarily delay value. |
Future Outlook: The Blueprint for Modern Data Consolidation
For mid-market enterprises prepared to transition away from accidental architectures toward unified data management platforms, success requires a disciplined evaluation methodology that prioritizes operational reality over feature checklists.
Evaluating Platforms Beyond the Spec Sheet
When assessing unified data platforms (such as modern all-in-one data management ecosystems offered by providers like BEEM), procurement teams should focus on operational criteria that directly impact governance and team velocity:
- Support Model: Is there a dedicated customer success and engineering support structure available when pipelines fail, or is the ecosystem entirely self-serve? For lean mid-market teams lacking dedicated data engineering departments, responsive external support protects internal bandwidth and maintains data quality standards.
- Breadth of Native Connections: Does the platform natively support the software stack the business already relies on, or will custom integration work be required on day one? Native connectivity ensures that data quality rules and access control policies can be enforced immediately at the source.
- Time-to-Value: How rapidly can the team produce a verified, working report in a live environment? Accelerated time-to-value ensures that governance improvements and data reliability gains become visible quickly, securing organizational buy-in.
The Concrete Migration Acceptance Test
To validate whether consolidation has successfully resolved historical friction, organizations should implement a rigorous operational acceptance test using their next disputed report.
Before retiring legacy workflows, have marketing and finance run the exact same agreed-upon calculation against the raw source records within the newly consolidated platform. Compare the results side-by-side. Formally record the designated owner of the calculation and the automated validation rule designed to catch failed data checks. If numerical discrepancies persist, trace the variance through the connection and transformation pipelines before migrating additional business units into the ecosystem.
By treating data architecture not as a collection of isolated software purchases, but as a governed, unified utility, mid-market enterprises can finally transform their data from an operational liability into a durable competitive advantage.