Executive Overview
For decades, the mechanics of web search have relied on a relatively transparent ecosystem. When a user typed a query into Google, the search engine returned a list of direct, unmasked destination URLs. For humans, this meant a frictionless path to publishers, e-commerce platforms, and information repositories. For machines—including search engine optimization (SEO) rank-trackers, aggregators, data scrapers, and generative artificial intelligence (GenAI) agents—it provided an open door to index, harvest, and analyze the web at scale.
That open door is now firmly swinging shut.
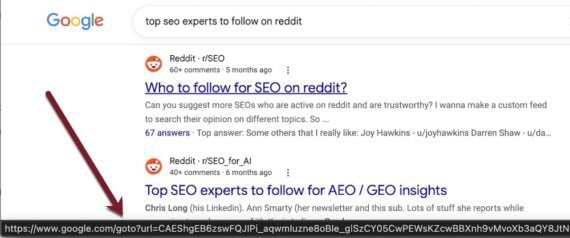
Google is rolling out a major structural shift across its Search Engine Results Pages (SERPs), replacing direct destination URLs with intermediate google.com/goto redirect links for logged-out users. Following a test phase that began in July, this rollout is expanding to the vast majority of logged-out search sessions.
This move is not an isolated design tweak; it is the latest salvo in Google’s escalating war against automated bot traffic. Facing unprecedented server loads driven by automated rank-tracking tools and resource-hungry GenAI models scraping real-time data to answer user prompts, Google is systematically raising the cost of programmatic access.
For digital marketers, SEO professionals, e-commerce merchants, and data analysts, the implications are profound. While major tracking suites like Ahrefs, Moz, and Semrush have largely adapted to the hurdle, smaller tools face immediate operational disruptions. Meanwhile, metrics within Google Search Console, third-party AI citation tracking, and the broader data intelligence ecosystem are bracing for turbulence. This article explores the mechanics of Google’s new redirects, the ongoing legal and technical battle against bots, and what this tectonic shift means for the future of search data visibility.
Detailed Chronology: How Google Closed the Open Web
Google’s friction-increasing strategy did not happen overnight. It represents a carefully calculated, multi-year escalation designed to regain control over its server infrastructure and intellectual property from automated scrapers and aggressive bots.
The Anatomy of the Problem
Google has struggled with bot-initiated search sessions almost since its inception, but the nature of the threat has evolved dramatically. Historically, bots were largely limited to web scrapers and directory builders. In the modern era, however, the ecosystem is flooded with two distinct types of high-volume automated traffic:
- Rank-Tracking Agents: Commercial SEO platforms that continuously query Google across millions of keywords to track organic rankings for enterprise clients.
- Generative AI Crawlers: Autonomous agents deployed by LLM developers that query Google in real-time to fetch up-to-date answers for user prompts, bypassing traditional crawling mechanisms by using the search engine itself as an API.
These automated sessions consume massive amounts of computational power, skew engagement metrics, and, in Google’s view, siphon off value without contributing to the underlying web ecosystem.
Step One: Killing the &num=100 Parameter
Last year, Google made its first major structural move to deter high-volume scrapers by canceling the &num=100 URL parameter. Historically, this parameter allowed power users and automated bots to request up to 100 organic search listings per results page.
By eliminating this option and forcing default pagination (typically 10 results per page), Google dramatically increased the operational costs for bots. To gather the same volume of ranking data, scrapers were forced to crawl ten times as many pages, multiplying their bandwidth consumption, processing overhead, and vulnerability to rate-limiting countermeasures.
Step Two: The Summer 2025 /goto Tests
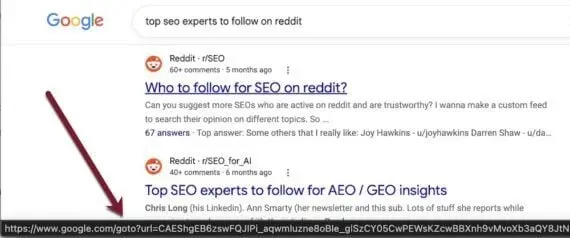
Building on the momentum of the pagination clampdown, Google began quietly testing google.com/goto redirects in July. Rather than rendering the raw, direct URL of the ranking web property in the HTML markup of the SERP, Google implemented an intermediate wrapper.
During the testing phase, SEO researchers and bot operators noticed that organic links were suddenly pointing to Google-controlled redirect scripts. This forced any automated tool attempting to extract target URLs to either execute JavaScript, parse intermediate HTTP headers, or physically click the links—actions that are significantly more difficult and resource-intensive to execute at scale than simple HTML parsing.
Step Three: The Broad Deployment
Following weeks of closed-beta testing and observation, Google signaled its intent to deploy these redirects globally to most logged-out users within a month. Because logged-out users represent the primary target pool for anonymous scrapers and public-facing AI agents, this deployment effectively neutralizes simple scraping scripts that do not authenticate or mimic complex browser sessions.
Supporting Context & Metrics: Navigating the Fallout
The implementation of google.com/goto redirects sends shockwaves through the digital marketing and SEO tool ecosystems. Understanding how different sectors are impacted requires examining the ground-level data and operational adjustments taking place across the industry.
Impact on Rank Trackers
For years, commercial rank-tracking tools relied on harvesting raw SERP HTML to map keyword positions to target URLs. The introduction of intermediate redirects breaks traditional parsing methods because the initial href attribute points to a Google domain rather than the destination property.
However, the major players in the SEO software industry have demonstrated remarkable agility:
- Ahrefs and Moz: Both platforms quickly identified Google’s testing phases during the summer and engineered algorithmic workarounds. Their current infrastructure successfully resolves the
google.com/gotowrappers to identify true target URLs without registering artificial drops. - Semrush: Early reports in August indicated that Semrush temporarily registered
google.com/gotolinks as ranking entries in certain data sets. However, within weeks, those artifacts largely disappeared, indicating that Semrush successfully deployed a parsing update to unwrap the redirects. - The Long Tail of SEO Software: While enterprise tools have adapted, smaller, bootstrapped, or proprietary rank-tracking software suites may lack the engineering resources to instantly pivot. Organizations relying on niche or in-house tracking scripts should expect temporary anomalies, including dramatic, artificial ranking drops or inflated redirect errors in their internal dashboards.
Search Console Performance Reports
For website owners and digital marketing agencies, Google Search Console (GSC) remains the gold standard for tracking organic visibility. Thus far, GSC "Performance" reports—which rely on first-party data captured directly within Google’s authenticated infrastructure—appear largely unaffected by the frontend redirect rollout.
Nevertheless, experts are monitoring two subtle, secondary effects that could skew reporting:
- Bot Noise Distortion: As AI agents and scraping bots alter their tactics to cope with
/gotolinks, their automated interaction patterns may create statistical noise in impression and click-through-rate (CTR) data. - Attribution Lag: Changes in how browsers handle intermediate redirects can occasionally cause micro-delays in telemetry dispatch, leading to slight synchronization variances in daily reporting updates.
Webmasters are advised to maintain a calm perspective; minor, temporary fluctuations in GSC numbers following infrastructure deployments are standard and rarely indicative of actual organic visibility loss.
The GenAI Citation Dilemma
Generative AI platforms that rely on Google search integration to retrieve real-time facts are facing an identity crisis. When these LLM agents query Google under the hood, they are now frequently retrieving and citing the google.com/goto URLs rather than the canonical web addresses of the original publishers.
While AI developers are actively updating their extraction pipelines to strip out or resolve these wrapper URLs, third-party AI citation tracking reports—which measure how often a brand is referenced by generative engines—may show artificial declines or corrupted attribution data in the interim.
Legal Battles and the Broader War on Data Scraping
Google’s technical countermeasures against automated crawling are mirrored by an aggressive legal strategy designed to protect its intellectual property and server infrastructure. The battle lines were drawn sharply in late 2025.
The SerpAPI Litigation
In December 2025, Google took unprecedented legal action by filing a lawsuit against SerpAPI in a U.S. District Court. SerpAPI is a prominent, commercial scraping service widely utilized by third-party developers—including enterprise applications and AI platforms like ChatGPT—to programmatically retrieve structured search results without maintaining their own scraping infrastructure.
Google’s legal complaint alleged that SerpAPI’s systematic harvesting of SERPs constituted a direct violation of the 1998 Digital Millennium Copyright Act (DMCA), alongside traditional claims of breach of terms of service and computer fraud.
In a notable early setback for the search giant, the presiding federal court tossed out Google’s lawsuit. However, demonstrating its absolute commitment to halting unauthorized data extraction, Google swiftly filed an amended complaint, recalibrating its legal arguments to survive judicial scrutiny.
A Macro Trend Toward Data Lockdown
The combination of technical hurdles like google.com/goto redirects and aggressive litigation against commercial scrapers highlights a definitive industry trend: the walled garden is expanding.
For over two decades, the open web operated on a tacit agreement that search engines indexed public content, and in return, users and third-party tools could freely inspect search results. Today, with the rise of extractive AI models that monetize search data without driving return traffic to publishers or compensating search engines, that social contract has collapsed.
Google is no longer willing to subsidize the infrastructure costs of competitors, AI developers, and tracking tools. The message from Mountain View is clear: access to search data is a managed privilege, not an inherent public right.
Future Outlook: What to Expect Next
As the digital landscape adjusts to the ubiquity of google.com/goto redirects, stakeholders across the digital economy must prepare for a more opaque, restricted data environment.
1. Fuzzier Reports and Higher Friction
Expect data scarcity to become the new normal. As Google continues to deploy technical barriers—whether through encrypted query parameters, JavaScript-heavy rendering, or intermediate redirect wrappers—the granularity of third-party search analytics will inevitably decline. SEO professionals must shift away from hyper-granular, daily rank tracking toward holistic metrics such as blended organic traffic, conversions, and brand visibility.
2. Escalating Arms Race in Bot Engineering
The cat-and-mouse game between Google’s anti-bot infrastructure and bot developers will only intensify. As basic scrapers are blocked by redirect wrappers, bot operators will transition toward increasingly sophisticated headless browsers, AI-driven interaction models, and residential proxy networks designed to mimic human browsing behavior precisely. In response, Google may eventually deploy advanced behavioral challenges, such as invisible CAPTCHAs, for suspicious logged-out sessions.
3. The Commoditization of Enterprise SEO Intelligence
Smaller SEO agencies and independent marketers who rely on affordable, off-the-shelf rank-tracking tools may find themselves at a disadvantage as compliance costs rise. Major enterprise platforms with dedicated engineering teams will absorb the cost of maintaining complex scraping infrastructures, further consolidating market power among top-tier SEO software providers.
Final Thoughts
Google’s deployment of google.com/goto redirects is much more than a cosmetic update to search result links. It is a calculated architectural barrier designed to protect server resources, curb resource-draining AI scrapers, and reclaim control over the search ecosystem. While enterprise tools have adapted to the turbulence, the broader ecosystem must brace for a future characterized by tighter data controls, reduced visibility, and an unyielding corporate defense of the world’s most valuable search engine.