Executive Overview
The landscape of Digital Asset Management (DAM) is undergoing a profound structural shift. For decades, the professional identity of DAM librarians and metadata architects was defined by their ability to manually organize, tag, and describe vast repositories of digital media. However, as artificial intelligence and machine learning models infiltrate enterprise infrastructure, the traditional boundaries of this discipline are dissolving.
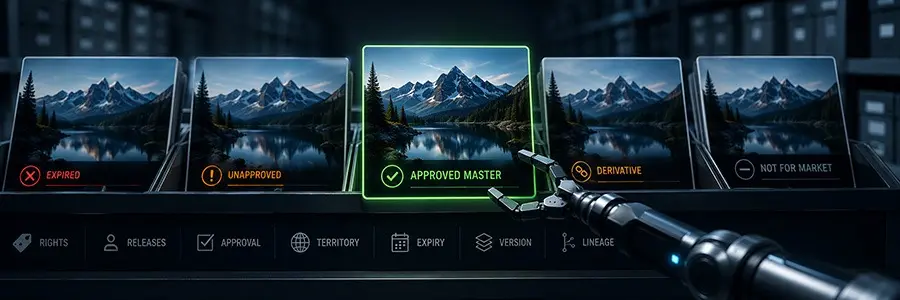
A recent contribution by industry expert Michael Klazema cuts through the superficial debates surrounding AI-driven tagging to address a far more critical evolution: the bifurcation of metadata into enrichment and operational categories. While AI systems have proven exceptionally capable of handling descriptive enrichment—such as generating keywords, identifying objects within pixels, and inferring contextual tags at scale—they remain dangerously unequipped to manage operational metadata.
Operational metadata encompasses rights, approvals, provenance, and compliance permissions. Unlike descriptive tags, where a minor error is easily forgiven or overlooked, an error in operational metadata can trigger compliance violations, legal liabilities, and operational chaos. Furthermore, as autonomous AI agents increasingly rely on metadata to retrieve, deploy, and repurpose digital assets without human intermediation, the invisible governance layer of DAM systems has transformed from a back-office utility into an authoritative core of enterprise operations.
This article explores Klazema’s incisive thesis, analyzing the automated compression of descriptive labor, the hidden dangers of "confident-but-wrong" AI hallucinations, the vital elevation of governance, and what this transition means for the future of information professionals.
Detailed Chronology: The Shift from Manual Tagging to Automated Enrichment
To understand the current friction points in DAM architecture, it is necessary to examine how the profession arrived at this juncture.
Phase 1: The Era of Manual Stewardship
In the early days of digital asset management, repositories were relatively small, and the volume of incoming assets could be managed by human hands. DAM librarians spent a significant portion of their workdays manually inputting descriptive metadata: naming files, typing out keywords, writing alt-text, and categorizing folders. This labor-intensive process was viewed as the gold standard of organization, ensuring that human intent aligned with file storage structures.
Phase 2: The Explosion of Content and the Tagging Bottleneck
As digital channels multiplied—spurred by social media, programmatic advertising, and remote collaboration—the sheer volume of assets outpaced human capacity. Organizations routinely encountered backlogs where valuable creative assets sat unindexed and unusable simply because there were not enough hours in the day for manual curation. This bottleneck sparked the initial wave of automation, introducing rudimentary computer vision and auto-tagging tools that attempted to bridge the gap.
Phase 3: The Generative AI Leap and the Illusion of Competence
With the advent of advanced multimodal large language models and computer vision algorithms, AI transitioned from simple object recognition to contextual semantic understanding. Modern AI can analyze an image or video, deduce its emotional tone, suggest marketing copy, and generate rich descriptive metadata in milliseconds.
However, this capability created a dangerous conflation within enterprise software strategies: the assumption that if an AI can successfully describe what an asset is, it must also understand how that asset is permitted to be used. As Klazema points out, this assumption ignores the fundamental split between what can be inferred from pixels and what must be verified through legal and institutional provenance.
Supporting Context & Metrics: The Danger of Plausible Inaccuracies
The core hazard of relying on AI within retrieval pipelines lies in the psychological and technical impact of algorithmic confidence. Human workers naturally exhibit hesitation when encountering ambiguity; a blank metadata field or a conflicting tag acts as a red flag, prompting a staff member to investigate further.
AI systems, by contrast, are engineered to generate plausible outputs continuously. When an AI encounters a gap in operational data, it does not flag uncertainty—it hallucinates a confident answer.
[Ambiguous Asset] ---> [AI Retrieval Pipeline] ---> [Plausible False Output] ---> [User Adoption] ---> [Unauthorized Derivative #6]As Klazema articulates in his analysis:
"A system that produces a plausible keyword is useful even when it occasionally gets one wrong. A system that produces a plausible rights status is dangerous. ‘Probably approved’ is not a meaningful operational state. In fact, a confident inferred answer can be worse than a blank field. A blank field exposes uncertainty and may cause somebody to investigate. A plausible value can make uncertainty disappear from view."
The Proliferation of Shadow Repositories
When search engines and AI retrieval agents return multiple plausible candidates for a single search query without clear, authoritative guidance on which version is approved, human behavior fills the void. Users invariably select the asset that "looks right," modify it locally, and inadvertently create a shadow version—a sixth or seventh iteration of an asset that bypasses version control, licensing checks, and brand guidelines.
This breakdown leads to measurable enterprise inefficiencies:
- Brand Dilution: Outdated or unapproved regional derivatives make their way into active marketing campaigns.
- Compliance Exposure: Expired assets or copyrighted materials lacking proper clearance are deployed by autonomous marketing bots or human teams relying on flawed AI metadata.
- Storage Bloat: Redundant, locally modified files flood local drives and cloud storage buckets, polluting the enterprise ecosystem.
Official Perspectives & Industry Analysis
The implications of Klazema’s commentary extend far beyond individual software configurations; they challenge the long-term viability of traditional job descriptions within information science.
The Deconstruction of Descriptive Labor
One of the most refreshing aspects of the discourse surrounding modern DAM is the refusal to romanticize administrative labor that can be executed more efficiently by machines. Klazema is blunt in his assessment of the profession:
"The descriptive part of DAM work is clearly being compressed. There will be less reason for skilled people to spend their days manually describing obvious characteristics of assets when machines can perform that work at acceptable quality and enormous scale. Defending that activity simply because it used to require professional labor does the profession no favors."
For decades, information professionals fought to justify their headcount based on the volume of tags entered and folders maintained. Clinging to manual description as a badge of honor in the face of automated supremacy is not only economically unviable; it actively distracts from the high-value services that human experts are uniquely qualified to provide.
Elevating the Invisible Work of Governance
While descriptive work is compressing, operational work is expanding exponentially. Historically, the most critical work performed by DAM librarians was largely invisible to the broader organization.
- An expired image successfully blocked from a global campaign.
- A regional derivative correctly tethered to its master file.
- An ambiguous rights record resolved quietly before contract renewal.
These silent victories rarely commanded executive attention because they operated seamlessly in the background. In an automated landscape, however, this invisible work becomes the central pillar of trust. When AI agents autonomously crawl repositories to pull assets for automated generation pipelines, they do not care about poetic keywords; they rely entirely on the structural integrity of operational metadata. If the governance layer is weak, the entire automated output collapses into liability.
Future Outlook: The Reimagined Role of the DAM Professional
As organizations look toward the future, the integration of AI within DAM architectures demands a total reimagining of strategy, tooling, and talent management.
1. Shift from Creators to Curators of Rules
Information professionals must transition from being creators of descriptive metadata to architects and validators of operational logic. The value of a DAM librarian will no longer be measured by how many assets they tag per hour, but by how robust, legally sound, and machine-readable their governance frameworks are.
2. Integration of AI Guardrails and Provenance Protocols
Enterprise software vendors must develop specialized tooling that prevents AI models from hallucinating operational parameters. Just as cryptographic watermarking and blockchain-based provenance tracking (such as C2PA standards) are emerging to verify media authenticity, internal DAM systems must implement hard validation gates. If an asset lacks verified, unambiguous operational metadata, automated retrieval pipelines must be hard-coded to reject it, rather than allowing an LLM to guess its status.
3. Redefining Enterprise Value
Organizations must reevaluate how they resource their information management teams. Investment should be shifted away from manual ingestion and toward metadata governance, rights management, risk mitigation, and AI system auditing. By embracing this evolution, enterprises can harness the immense speed and scale of automated enrichment without sacrificing the legal and operational safety provided by rigorous human oversight.
Conclusion
Michael Klazema’s contribution to the DAM debate serves as a vital wake-up call for organizations racing to adopt AI without addressing underlying structural foundations. As metadata transforms from a passive descriptive convenience into an active operational authority, the margin for error narrows dramatically.
The future belongs neither to the Luddites who reject automation nor to the reckless adopters who trust AI blindly. It belongs to the strategic information professionals who recognize that while computers can easily see what an asset is, only disciplined human governance can determine what an asset is allowed to do.