Executive Overview
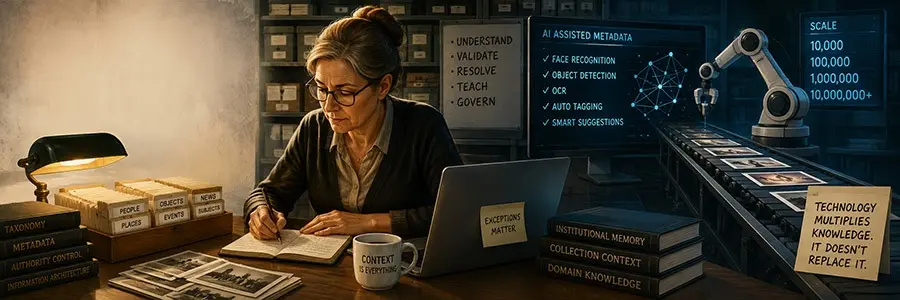
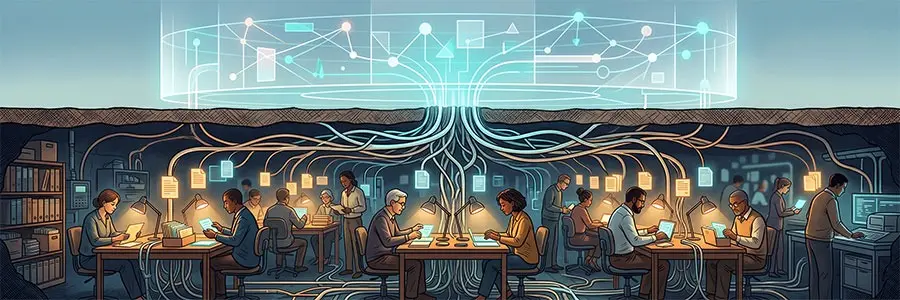
For as long as Digital Asset Management (DAM) has existed as a formal discipline, a dedicated workforce has sat behind graphical user interfaces (GUIs), performing the quiet, unglamorous, yet mission-critical labor of making digital assets findable. These information professionals—librarians, taxonomists, archivists, and metadata specialists—spend their careers tagging, describing, structuring, and correcting records. Their collective efforts form the invisible cognitive architecture that allows global enterprises, media conglomerates, and cultural institutions to navigate millions of digital assets seamlessly.
Today, however, that foundational paradigm is facing an unprecedented disruption. The rapid maturation of artificial intelligence—specifically multimodal computer vision, generative metadata models, and automated ingestion pipelines—promises to execute traditional cataloging tasks in mere seconds. What once required hours of human deliberation can now be achieved via algorithmic processing.
This technological leap begs a critical, industry-wide question: What happens to the human experts whose labor built these systems in the first place?
To address this pressing dilemma, DAM News has officially announced its editorial theme for the month, issuing a broad global call for contributions. The publication is seeking insights from information professionals, enterprise DAM managers, archivists, and software vendors to explore the rapidly shifting—and potentially vanishing—role of the human librarian within an increasingly automated ecosystem.
Rather than relying on speculative marketing hype, this initiative aims to capture grounded, lived experiences from the front lines of enterprise digital asset management. As organizations race to integrate AI into their operational workflows, the industry stands at a foundational crossroads. Is automation genuinely displacing human labor, or is it merely shifting professionals upward into oversight, quality control, and taxonomy governance? Does AI genuinely eliminate the need for skilled metadata work, or does it simply relocate human effort—hiding it behind complex models that still require constant training, auditing, and correction by domain experts?
Detailed Chronology: From Manual Tagging to Algorithmic Autonomy
To understand the current tension between human labor and machine intelligence, it is helpful to trace the evolution of metadata management within the digital asset lifecycle.
Phase One: The Era of Pure Manual Curation (Pre-2010s)
In the early days of enterprise DAM adoption, assets were cataloged almost entirely by hand. Librarians and archivists manually entered keywords, populated Dublin Core or custom schema fields, and structured folder trees based on rigid institutional taxonomies. While labor-intensive, this approach ensured high semantic accuracy and contextual relevance. The institutional knowledge of the organization lived directly inside the heads of these information professionals.
Phase Two: Semi-Automated Workflows and Controlled Vocabularies (2010s–2020)
As digital repositories expanded into terabytes and petabytes, manual entry became unsustainable. The industry introduced batch processing, controlled vocabularies, and rule-based automation. While macros and rudimentary scripts could apply bulk metadata tags, human intervention remained essential for complex contextualization, rights management, and disambiguation.
Phase Three: The Generative AI and Auto-Tagging Disruption (2020–Present)
The current era is defined by the integration of Large Multimodal Models (LMMs) and computer vision algorithms capable of analyzing images, videos, and audio files with astonishing speed. Modern DAM platforms now boast native auto-tagging features that can instantly identify objects, sentiment, facial expressions, and scenes within an asset.
This technological trajectory has drastically compressed the time-to-discover metric. However, it has simultaneously introduced profound institutional anxieties. When an algorithm automatically tags an asset, it operates on statistical probability rather than deep organizational context. Consequently, the industry is witnessing a cultural and structural pivot. Organizations are beginning to question the headcount allocated to traditional cataloging teams, prompting widespread debates regarding the future value of human expertise.
Supporting Context & Metrics: The Realities of AI in the Enterprise
While software vendors heavily market AI as a turnkey solution that completely automates digital asset pipelines, enterprise reality is far more nuanced. Industry analysts note that while auto-tagging scales efficiently, it frequently introduces distinct systemic challenges.
The Metadata Quality Problem
Automated systems are notoriously prone to hallucinations, cultural misinterpretations, and a lack of domain-specific nuance. For example, a generic computer vision model might successfully tag a historical photograph as "people outdoors," but completely fail to recognize the political significance, proprietary product terminology, or copyright restrictions associated with the subjects.
Without human oversight, these inaccuracies propagate silently through the enterprise database, resulting in corrupted search results and "dark data"—assets that are technically tagged but practically undiscoverable due to low-quality metadata.
Shifting Labor or Hidden Labor?
A central thesis of the upcoming DAM News editorial focus is the concept of relocated labor. Proponents of automation argue that human workers are being liberated from tedious, repetitive data entry. However, critics counter that this labor has not disappeared; it has merely been transformed into invisible oversight.
Librarians are increasingly being tasked with cleaning up AI-generated messes, auditing training datasets, fine-tuning taxonomies, and monitoring algorithmic drift. This raises an urgent professional question: Are these new responsibilities empowering information professionals, or are they devaluing traditional library science skills under the guise of modernization?
Perspectives from the Front Lines: A Call for Contributions
DAM News is explicitly inviting contributions that move beyond high-level vendor narratives and dive into the grounded realities of enterprise transformation. The publication has outlined several core areas of inquiry for potential contributors:
- Structural Restructuring: Has your organization reduced, restructured, or expanded its librarian and metadata teams following the adoption of AI-driven tools?
- Quality Control Crises: Have you encountered instances where automation produced catastrophic metadata quality issues that only a trained archival eye could catch and rectify?
- The Politics of Job Titles: Are information professionals being shoehorned into newly minted corporate titles such as "AI Trainer," "Prompt Engineer," or "Taxonomy Strategist"? Do these titles accurately reflect the depth of traditional information science skills, or are they corporate semantic maneuvers?
- Advocacy and Resistance: We welcome perspectives from professionals who have successfully redefined their organizational value, as well as those actively pushing back against the narrative that human curation is becoming obsolete.
Contributions are encouraged from across the broader DAM-aligned ecosystem, including information science, metadata strategy, workforce development, corporate governance, vendor product strategy, and organizational politics.
Future Outlook: Reclaiming the Value of Information Science
As organizations look toward the horizon of enterprise technology, the relationship between artificial intelligence and human curation will undoubtedly continue to evolve. The prevailing consensus among forward-thinking information architects is that AI will not entirely replace the DAM librarian; rather, it will bifurcate the discipline.
On one side, routine, low-level cataloging will be largely absorbed by automated pipelines. On the other side, the strategic management of meaning—governing taxonomies, designing context-aware ontologies, preserving institutional memory, and ensuring ethical compliance—will become more vital than ever. Algorithms require data to learn, but they lack the intrinsic understanding of human culture, business strategy, and historical context required to build truly resilient digital ecosystems.
If the invisible workforce of DAM librarians is to survive and thrive in this automated era, their expertise must be recognized not merely as a cost center for manual data entry, but as the foundational governance layer that keeps enterprise AI grounded in reality.
Submission Guidelines for Interested Contributors
For those wishing to share their insights, case studies, or critical perspectives, DAM News has established specific criteria for submissions:
- Word Count: Articles must be a minimum of 800 words.
- Exclusivity: Submissions must be exclusive to DAM News and non-promotional in nature.
- Editorial Standards: All pieces must adhere to the publication’s official editorial guidelines.
- Submission Contact: Please direct all article pitches and completed drafts to [email protected].
Note: DAM News reserves the right to modify submissions to ensure compliance with its editorial guidelines, with prior notification given to authors for any necessary revisions. Successful contributions will include direct links to the author’s or their company’s official website and/or LinkedIn profile.