Executive Overview
The rapid integration of artificial intelligence into enterprise workflows has fundamentally altered the operational reality of Digital Asset Management (DAM). For decades, organizations have built their repositories around a relatively straightforward philosophy: if an asset is stored securely, tagged correctly, and boasts a verifiable origin story, it is fit for deployment.
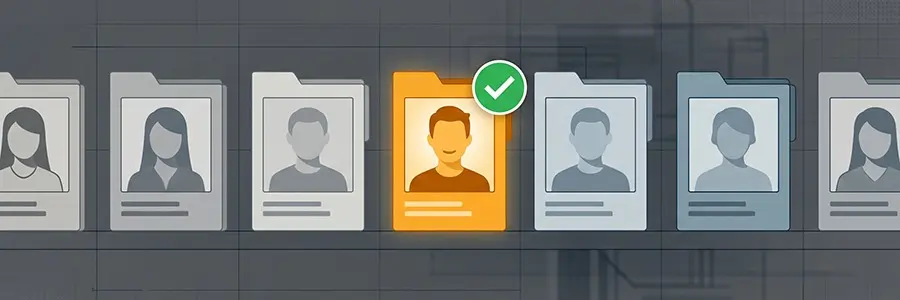
However, a recent conceptual contribution by industry expert Joshua Brown highlights a dangerous vulnerability in this legacy architecture. Through a deceptively simple anecdote—an AI publishing workflow that seamlessly retrieved an outdated, yet entirely genuine, headshot of Brown and propagated it across multiple drafts before human oversight caught the error—he exposes a systemic flaw. The DAM did not fail because it suffered a data corruption event or generated a synthetic hallucination. It failed because it conflated authenticity with authority.
As organizations increasingly transition from human-driven search-and-retrieve models to agentic AI workflows—autonomous software agents that actively execute multi-step tasks rather than merely presenting options to human operators—this conflation transforms from a minor inconvenience into a high-stakes operational safety issue. When algorithms operate at machine speed and scale, the traditional assumption that a findable asset is a usable asset collapses.
To bridge this gap, Brown proposes moving beyond traditional provenance tracking toward a robust "canonical authority state" framework. This article investigates the implications of this shift, analyzing the limitations of legacy DAM architectures, evaluating the proposed five-part state model, and examining what it takes for enterprises to prepare for an autonomous future where authentic is not current, findable is not approved, and stored is not publishable.
Detailed Chronology: The Evolution and Exposure of DAM Vulnerabilities
The Era of Static Repositories and Human Gatekeepers
To understand why the "headshot incident" serves as a watershed moment for DAM design, one must examine how traditional repositories evolved. For the past twenty years, DAM systems were engineered primarily as sophisticated file cabinets. They prioritized storage, format conversion, keyword tagging, and permission management.
In these legacy environments, the final arbiter of asset quality was always a human. A marketing manager searching for an executive photo would pull up a half-dozen options, visually verify that a particular headshot was recent, check with communications regarding rights compliance, and manually drag the file into a content management system.
If an outdated asset sat alongside a current one, the human brain typically served as the safety net, filtering out superseded materials based on institutional memory or visual cues. The system’s job ended at retrieval; whether the asset should actually be used in the present tense was left entirely to human discretion.
The Rise of Agentic AI and Autonomous Workflows
The introduction of agentic AI systems shatters this human-in-the-loop safety net. Unlike traditional search tools that return a list of ranked links or files for human perusal, autonomous agents execute tasks end-to-end. An AI publisher tasked with creating a newsletter, updating executive biographies, or generating a multi-channel social media campaign will query the DAM, select an asset, format it, and publish it without human intervention.
When an AI agent interacts with a legacy DAM, it evaluates assets based on metadata matching, vector embeddings, and semantic relevance. It does not possess institutional memory. It cannot look at a headshot and deduce that the subject has aged out of that look, grown a beard, or changed their corporate role.
If the outdated file possesses flawless metadata—such as high resolution, accurate IPTC tags, and a valid author credit—the AI evaluates it as an authentic object. By pulling that asset into a live workflow, the system mistakes its historical validity for current operational authority. As Brown succinctly notes:
"The interesting failure was not image generation. It was not even search. The old image was an authentic image of the correct person. Its provenance could have been flawless. The failure was that authenticity had been mistaken for authority."
The Anatomy of the Breakdown
The publishing error involving Brown’s headshot underscores a fundamental divergence in questions. Traditional provenance frameworks are retrospective; they ask: "What happened to this object?" They track creation dates, editing histories, color profiles, and legal chains of custody using standards like W3C PROV or the Coalition for Content Provenance and Authenticity (C2PA).
Conversely, agentic workflows require prospective governance. They demand an answer to a fundamentally different question: "What may happen with this object now?"
When a repository fails to distinguish between historical fact and contemporary utility, autonomous agents become liability vectors. An AI cannot discern whether a press release asset from 2019 featuring a discontinued product line is a historical artifact or a current marketing asset unless the DAM explicitly encodes that distinction into its core metadata layer.
Supporting Context & Metrics: The Scale of the Digital Clutter Challenge
The Hidden Cost of Duplicate and Superseded Assets
The inability of DAM systems to manage canonical authority exacerbates an already massive enterprise problem: digital clutter. Industry benchmarks indicate that large organizations waste millions of dollars annually searching for, recreating, or mistakenly deploying outdated brand assets.
According to various enterprise content management studies:
- 30% to 50% of corporate digital assets stored in enterprise repositories are estimated to be duplicates, near-duplicates, or outdated versions of active files.
- Over 60% of knowledge workers report spending more than five hours a week searching for the correct file version, a friction point that multiplies exponentially when autonomous agents begin executing these searches at scale.
- Under 20% of DAM implementations enforce rigorous, automated lifecycle retirement policies for superseded collateral, leaving old brand logos, superseded product specifications, and deprecated executive imagery active within search indexes.
Search Relevance vs. Governance Failure
While Brown’s analysis focuses heavily on the distinction between authenticity and authority, it opens a broader debate within the information architecture community regarding the role of search.
Brown argues that the incident was not fundamentally a search failure, pointing out that the AI successfully located a genuine, relevant file matching the query parameters. However, critics of legacy DAM architectures suggest that dismissing search is premature. When an agent retrieves the wrong file from among dozens of plausible candidates, it exposes a critical flaw in relevance and ranking algorithms.
If a search engine or vector database surfaces an outdated asset ahead of a current one, or treats them as semantic equals, the retrieval mechanism shares the blame with the governance layer. Furthermore, if approval states, effective dates, and rights-based metadata are ignored—or poorly weighted—by the DAM when surfacing results, AI agents will inevitably inherit those blind spots.
Official Industry Perspectives and Proposed Frameworks
The Five-Part State Model for Canonical Authority
To address these vulnerabilities, Joshua Brown proposes a comprehensive, five-part state model designed to embed canonical authority directly into DAM architectures. Rather than inventing proprietary mechanisms from scratch, the framework builds upon existing open standards like W3C PROV and C2PA, translating historical provenance into a dynamic, present-tense decision layer.
The five core components of the model include:
- Canonical Identity: Establishing a master record or "golden record" for an entity or asset class, ensuring that variants, crops, and localized versions tie back to a single recognized source of truth.
- Supersession and Invalidation: Mechanically linking new assets to old ones so that the introduction of a current asset automatically invalidates or deprecates its predecessors within automated workflows.
- Scope of Approval: Defining precise contextual boundaries for where and how an asset may be deployed (e.g., internal-only, external press, social media, paid advertising) to prevent cross-channel compliance breaches.
- Rights and Consent State: Dynamically tracking licensing expiration dates, talent release forms, and geographical restrictions in real-time, locking out assets whose legal parameters have lapsed.
- Render Verification at the Point of Output: Implementing a final validation check immediately before an asset is published or rendered, confirming that its authority state remains valid at the exact millisecond of deployment.
A Lightweight Model for Smaller Teams
Recognizing that enterprise-grade implementations of W3C PROV and complex multi-variable state engines can overwhelm resource-constrained organizations, Brown also proposes a streamlined, pragmatic alternative for smaller teams. This lightweight framework collapses governance into three actionable operational states:
- ACTIVE: The asset is current, verified, and fully cleared for autonomous or manual deployment within specified scopes.
- SUPERSEDED: The asset remains in the repository for historical or archival reference, but automated workflows and AI agents are strictly hard-coded to ignore it in favor of its designated successor.
- ARCHIVAL: The asset is retired from active circulation, subject to retention policies, and locked against any form of publishing or distribution.
Combined with a clear effective date and explicit approved uses, this simplified schema offers an accessible entry point for organizations looking to bulletproof their asset repositories without overhauling their entire IT infrastructure.
Future Outlook: Preparing DAMs for the Agentic Enterprise
The Hard Realities of Implementation
While the theoretical elegance of the five-field model is undeniable, enterprise software deployment rarely proceeds without friction. Integrating W3C PROV revision and invalidation semantics into a real-time decision layer represents a massive engineering challenge.
Many corporate DAM teams already struggle with basic metadata hygiene—such as enforcing mandatory tagging, maintaining controlled vocabularies, and managing user permissions. Expecting these same teams to adopt sophisticated canonical authority states will require a cultural shift as much as a technological upgrade. As industry observers note, the confidence behind theoretical governance models can sometimes underestimate the sheer messiness of human-generated content creation.
The Imperative of "Zero-Trust" Asset Management
As autonomous agents evolve from experimental novelties into core components of enterprise operations, the philosophy governing digital assets must shift toward a "zero-trust" model. In a zero-trust DAM environment:
- No file is assumed to be current simply because it exists in the system.
- No asset is assumed to be approved for publishing simply because it matches a semantic search query.
- No provenance is considered complete unless it includes real-time validation of current authority and active rights.
The lesson of Joshua Brown’s errant headshot is a warning sign for the entire digital asset management industry. As machines take over the steering wheel of content creation and distribution, repositories can no longer afford to be passive warehouses of authentic objects. They must become active arbiters of organizational truth, ensuring that what is stored, found, and published represents the exact reality of the enterprise today—not a relic of its past.