Executive Overview
For years, the trajectory of artificial intelligence has been dictated by a simple, expensive, and resource-heavy rule: bigger is better. To build reasoning models capable of complex deduction, advanced coding, and contextual logic, AI labs have traditionally relied on massive server farms, thousands of specialized graphics processing units (GPUs), and multi-billion-parameter footprints that demand cloud-based deployment.
Enter PrismML, an emerging AI laboratory that is aggressively flipping the industry script. While the broader tech ecosystem remains captivated by eye-watering venture capital rounds and hyperscale data center expansions, PrismML has quietly operated with a modest $22.25 million seed round. Yet, it is fast becoming one of the most talked-about technical powerhouses in Silicon Valley and academic research circles alike.
PrismML’s core thesis is simple yet disruptive: capable, high-performing reasoning large language models (LLMs) do not need to be massive.
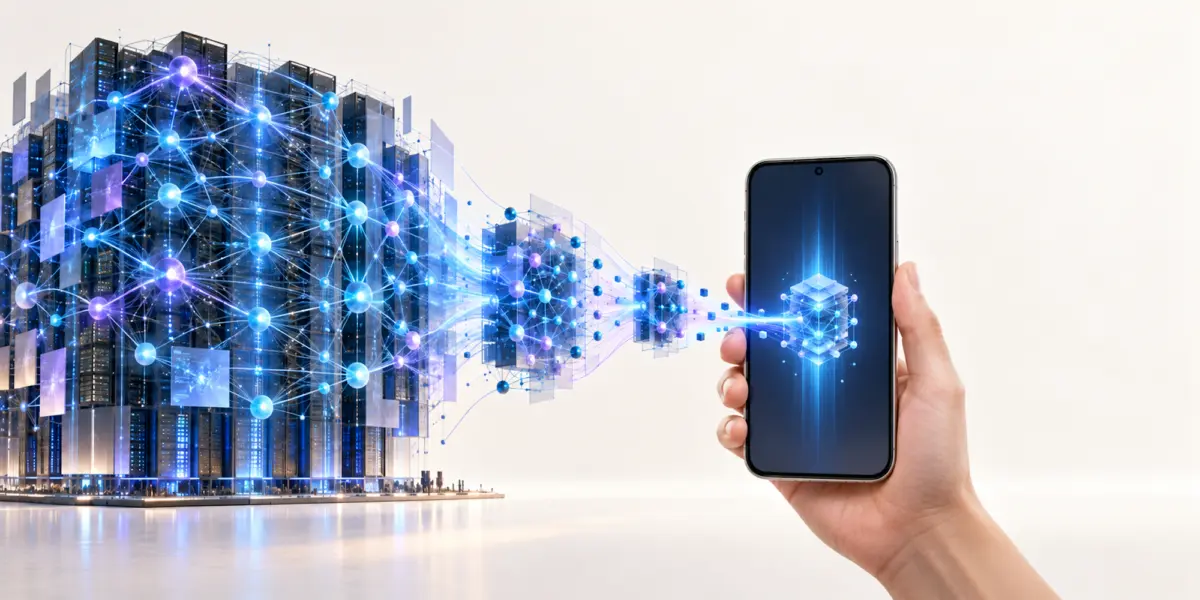
Through breakthroughs in mathematical model compression, the startup is developing reasoning models so compact they can run seamlessly on consumer-grade hardware—personal computers and even high-end smartphones. This shift promises to decentralize artificial intelligence. Instead of routing sensitive prompts through centralized cloud infrastructure, users could soon execute sophisticated reasoning tasks locally on their own devices. This paradigm shift offers a dual promise that has tech giants taking notice: absolute user privacy and zero recurring cloud inference costs.
This deep-dive investigation explores PrismML’s technical architecture, its leadership lineage rooted in Caltech and UC Berkeley, the debut of its flagship Bonsai 2 model, and the commercial implications of bringing device-level intelligence to the masses.
Detailed Chronology: From Academic Lab to Edge-AI Disrupter
The genesis of PrismML is anchored in rigorous academic research rather than a rush to commercialize half-baked tools. Founded by a cohort of distinguished Caltech researchers, the startup is helmed by Babak Hassibi, a prominent Caltech professor and an internationally recognized authority in compression technologies, signal processing, and algorithms.
The company’s pedigree extends deep into the infrastructure of modern AI. PrismML counts Ion Stoica as a strategic adviser. Stoica is a towering figure in computer science: a co-founder of data powerhouse Databricks and the director of UC Berkeley’s legendary Sky Computing Lab. The Sky Computing Lab has historically served as an incubator for some of the most influential technologies and startups of the modern cloud and AI era, including Letta and SGLang.
Key Milestones in PrismML’s Evolution
- The Conceptual Phase: Recognizing the severe latency, privacy, and economic bottlenecks of cloud-hosted LLMs, the founding team at Caltech began experimenting with radical weight-reduction paradigms that move far beyond standard quantization.
- March (Early 2026): PrismML releases its first iteration of the Bonsai model family. Despite being an early proof-of-concept, the model successfully matches 95% of its parent model’s aggregate benchmark scores while drastically cutting memory overhead. The open-source community responds with staggering enthusiasm: the initial Bonsai model is downloaded over 11 million times, while even smaller companion variants pick up another 2.6 million downloads.
- The Seed Funding Round: Backed by prominent institutional heavyweights including Khosla Ventures, Cerberus Capital, and Caltech itself, PrismML secures $22.25 million in seed funding—a remarkably modest sum compared to the multi-billion-dollar valuations of contemporary foundation model builders.
- July 2026: Rumors swirl across tech media outlets regarding high-level strategic discussions between PrismML and consumer tech titan Apple concerning advanced on-device AI compression frameworks for future generations of the iPhone. While CEO Babak Hassibi declines to comment directly on these talks, industry analysts view the rumored partnership as a logical validation of PrismML’s hardware-agnostic mission.
- Late August (Thursday Release): PrismML formally releases Bonsai 2 27B, its most advanced and commercially viable model to date. Compressing Alibaba’s widely utilized open-source Qwen3.8 27B down to a mere 5.9 GB, the release proves that high-density reasoning can fit comfortably within standard PC and high-end mobile memory constraints.
Supporting Context & Metrics: Decoding the Math Behind Bonsai 2
To understand why PrismML is turning heads, one must look closely at the mechanical engineering of large language models.
The Physics of Model Weights
Traditional LLMs operate via "weights"—numerical values learned and stored during the training phase that dictate how the neural network maps inputs to outputs. In standard precision configurations, each weight typically demands 16 bits of memory. Across billions of parameters, this requirement balloons into tens or hundreds of gigabytes of storage, demanding specialized data-center-grade accelerators (such as NVIDIA H100s or B200s) just to load the model into active memory (VRAM).
PrismML sidesteps this bottleneck through a mathematically rigorous approach known as "ternary weights." Instead of floating-point representations or standard 4-bit/8-bit quantization, PrismML simplifies each weight down to just three discrete values:
- $+1$
- $-1$
- $0$
By stripping away the superfluous precision while preserving the underlying structural hierarchy of the neural network, PrismML achieves dramatic space savings without fundamentally breaking the network’s semantic logic.
Benchmarks and Performance Parity
| Metric / Feature | Original Qwen3.8 27B | PrismML Bonsai 2 27B | Improvement / Delta |
|---|---|---|---|
| Model Footprint (Size) | ~50+ GB (Uncompressed) | 5.9 GB | ~9x to 10x memory reduction |
| Hardware Compatibility | Cloud Server / High-End GPU | PCs & High-End Smartphones | Device-level deployment enabled |
| Benchmark Retention | 100% (Baseline) | 98% Aggregate Parity | Up from 95% in the March release |
| Global Download Volume | N/A | 13.6+ Million Total (Across all variants) | Rapid organic developer adoption |
As detailed in the metrics above, Bonsai 2 successfully recovers 98% of the aggregate benchmark performance of the original Qwen model. This represents a measurable leap forward from the 95% parity achieved by the first-generation Bonsai model released just months prior in March.
Official Statements and Industry Insights
The implications of PrismML’s technical architecture extend far beyond academic benchmarks. Industry leaders are beginning to recognize that efficient edge-AI deployment could fundamentally alter the economics of software development.
Babak Hassibi on the Limits of Compression and Scaling
Addressing the gap between compressed and uncompressed models, CEO Babak Hassibi acknowledges that compression will likely always introduce some degree of trade-off. However, he emphasizes that perfection in benchmark scores is largely an academic pursuit:
"The next models that we will release, hopefully in the next couple of months, will be in the several-hundred-billion-parameter range, and I expect it will be easier to retain the intelligence there. As model size grows, there is more room to be able to compress them without losing the intelligence. So I would just say, as a general trend, for larger models, it’s easier to get to 100%."
Hassibi’s observation points to an encouraging architectural reality: massive foundational models possess massive functional redundancy. When scaling up into the hundreds of billions of parameters, a high percentage of weights act as supportive scaffolding rather than critical information nodes. Compressing these ultra-large models actually yields higher fidelity retention because the underlying intelligence is distributed across a broader statistical landscape.
Ion Stoica on User Sovereignty and Privacy
Adviser Ion Stoica highlights the profound societal benefits of moving advanced intelligence from centralized server silos directly onto local consumer hardware:
"You are going to have intelligence at your fingertips, and it’s going to be free because it’s going to run on the device you already bought. It’s also going to be private, because you’re not going to send it to the cloud."
In an era defined by growing regulatory scrutiny over data privacy, corporate surveillance, and the exorbitant electrical grid demands of hyperscale AI data centers, Stoica’s vision positions PrismML as a champion of decentralized computing. Users no longer need to compromise their personal data, medical records, or proprietary corporate codebases by uploading them to third-party cloud servers just to leverage advanced reasoning capabilities.
Future Outlook: The Road Ahead for Edge Reasoning
As PrismML prepares for its next major evolutionary phase—targeting models in the several-hundred-billion-parameter range—the startup stands at a fascinating crossroads in the artificial intelligence landscape.
While well-funded competitors like Multiverse Computing pursue alternative compression pathways with massive war chests, PrismML has proven that mathematical elegance, exceptional academic guidance, and lean operational discipline can yield industry-leading results.
Several critical questions remain for the months ahead:
- Reaching the 100% Threshold: Will PrismML’s forthcoming ultra-large model compression techniques successfully achieve absolute parity with uncompressed frontier models, eliminating any remaining performance degradation?
- Hardware Ecosystem Integration: Beyond rumored discussions with Apple, how quickly will major smartphone manufacturers and PC original equipment manufacturers (OEMs) natively integrate ternary-weight execution runtimes into mobile system-on-chips (SoCs) and neural processing units (NPUs)?
- The Harness Factor: As industry analysts increasingly note that the surrounding software harness—not just the raw model itself—determines practical task accuracy, how will PrismML optimize its models to integrate with emerging agentic frameworks and developer tooling?
One thing is certain: the era of purely cloud-dependent artificial intelligence is facing a serious challenger. By proving that advanced reasoning can be packed into a 5.9 GB file running locally on everyday hardware, PrismML is not merely optimizing code—it is democratizing access to intelligence itself.