Executive Overview
As enterprise digital ecosystems shift rapidly from human-led content curation to automated, agentic AI workflows, a foundational vulnerability in modern Digital Asset Management (DAM) platforms has been laid bare. A recent, highly discussed contribution by industry expert Joshua Brown highlights a deceptive operational trap: the dangerous conflation of authenticity with authority.
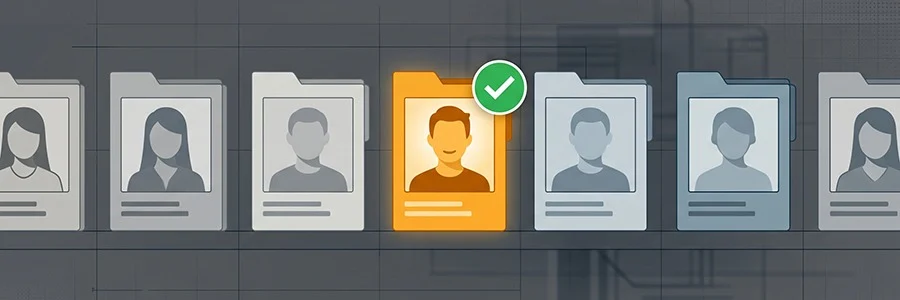
To illustrate this peril, Brown shares a telling personal anecdote. An automated AI publishing pipeline recently scraped and deployed an outdated professional headshot for him. The image was entirely genuine—it was a real photograph of Brown, and its technical provenance was virtually flawless. Yet, it was completely wrong for the context, representing a superseded iteration of his professional branding. Because the system could verify that the file was authentic, it assumed the asset possessed the authority to be published.
This seemingly minor editorial mishap serves as a powerful microcosm for a much larger enterprise crisis. In a world where AI agents act autonomously—making decisions, selecting media, and distributing content at unprecedented speeds and scales—traditional DAM architectures are no longer fit for purpose. When machines stop merely presenting options to human operators and instead execute publishing tasks independently, structural gaps in metadata governance turn into high-speed operational, legal, and brand safety hazards.
To resolve this, Brown proposes a transition away from retrospective tracking toward a proactive governance framework anchored in canonical authority. By distinguishing between what an object is (provenance) and what may legally and operationally be done with it now (authority), organizations can build the guardrails necessary to survive the agentic revolution. However, bridging the gap between theoretical five-part state models and messy, real-world DAM implementations remains one of the most formidable challenges facing content operations today.
Detailed Chronology: The Evolution of the Asset Lifecycle and the Agentic Disruption
To understand why traditional DAM architectures are struggling under the weight of generative and agentic AI, it is necessary to examine how content has historically moved through enterprise systems—and where the friction points have multiplied.
Phase 1: The Era of Static Repositories and Human Gatekeeping
For decades, Digital Asset Management systems functioned primarily as digital filing cabinets or secure warehouses. Assets—ranging from raw photography and brand logos to finalized marketing copy—were ingested, tagged with descriptive metadata, and stored.
- The Workflow: A human content creator or marketer would log into the DAM, run a keyword search, manually review search results, evaluate visual quality, check rights management notes, and download the asset for manual insertion into a CMS, social scheduler, or layout software.
- The Safeguard: Human intuition acted as the ultimate circuit breaker. If a photograph was ten years old, a human editor would instinctively recognize that the subject’s appearance had changed or that the campaign context was obsolete, bypassing the file regardless of how easily searchable it might be.
Phase 2: The Proliferation of Metadata and Fragmented Repositories
As digital channels multiplied, the volume of content exploded. DAM platforms evolved to incorporate complex taxonomies, rights-management modules, and version-control histories.
- The Complication: Teams began generating hundreds of iterations of the same core asset (localized variants, cropped formats, compressed web files, and vector exports).
- The Vulnerability: While systems became better at tracking provenance (the historical lineage of a file, often supported by standards like W3C PROV and C2PA), they struggled to cleanly communicate current operational state. Superseded files frequently remained active in search indices, lingering alongside newer iterations due to loose tagging or inconsistent archival protocols.
Phase 3: The Shift to Autonomous, Agentic AI Workflows
We have now entered the agentic era, where AI systems do not wait for human permission to retrieve and deploy assets. Large Language Models (LLMs) and specialized multimodal AI agents operate inside enterprise workflows, executing end-to-end content production cycles autonomously.
- The Autonomous Loop: An AI agent is tasked with generating a weekly newsletter, a series of social media posts, or a dynamic web page. It queries the enterprise DAM, extracts files matching semantic search criteria, evaluates them against prompt parameters, and publishes them directly to production environments.
- The Breaking Point: Because AI agents lack human intuition and contextual common sense, they optimize for match probability rather than temporal relevance or strategic authority. If an asset is authentic, easily accessible via search, and technically compliant, the agent treats it as viable. As Joshua Brown’s anecdote demonstrates, this operational blind spot allows obsolete assets to bypass human review entirely, introducing systemic risk to enterprise brand integrity.
Supporting Context & Metrics: The Anatomy of DAM Failures in the Age of AI
The friction between legacy asset management and modern AI automation is not merely a theoretical concern; it is backed by growing operational friction within enterprise content teams. Industry data and enterprise feedback underscore the urgency of addressing metadata blind spots.
The True Cost of Cluttered Repositories
According to recent enterprise content operations benchmarks:
- Over 40% of digital assets stored in enterprise repositories are estimated to be duplicates, near-duplicates, or outdated versions of active files.
- Up to 25% of marketing teams report instances where discontinued branding, deprecated logos, or retired product imagery have accidentally made their way into live public-facing campaigns due to automated publishing tools.
- The Search Paradox: Modern AI-driven semantic search has made asset retrieval faster than ever, but speed without governance exacerbates the problem. When an agent can query millions of files in milliseconds, the probability of selecting a technically valid yet strategically unauthorized asset scales exponentially.
Analyzing the Core Distinctions
To grasp why current DAM configurations fail, Brown breaks down the conceptual boundaries that systems routinely conflate:
- Authenticity vs. Authority:
- Authenticity guarantees that an asset is genuine, unmanipulated, and properly attributed to its source (often verified via cryptographic watermarking and provenance standards like C2PA).
- Authority determines whether that authentic asset is currently sanctioned, legally cleared, and strategically appropriate for deployment today.
- Findability vs. Approval:
- A file can easily surface at the top of a semantic search engine results page (SERP) due to robust tagging, while simultaneously violating current regional licensing agreements or brand guidelines.
- Storage vs. Publishability:
- Archival and historical retention policies require organizations to store legacy assets for compliance, auditing, or historical record-keeping. However, storage permanence must never imply public publishability.
The Proposed Frameworks: From Complex Theory to Lightweight Reality
To operationalize canonical authority, Brown presents two distinct implementation models tailored to different organizational scales.
1. The Comprehensive Five-Part State Model
For enterprise-grade environments managing complex, multi-channel, global operations, Brown proposes integrating existing technical standards (such as W3C PROV) into a present-tense decision layer encompassing:
- Canonical Identity: Definitive tracking of the core asset and its unique lineage.
- Supersession and Invalidation: Automated flags that immediately downgrade an asset’s status the moment a newer iteration is approved.
- Scope of Approval: Granular metadata defining where, when, and how an asset may be utilized (e.g., restricted to specific geographic regions or marketing channels).
- Rights and Consent State: Dynamic monitoring of licensing expirations, model releases, and usage agreements.
- Render Verification: Real-time validation checks executed at the exact point of output to ensure no unauthorized transformations have occurred.
2. The Lightweight Operational Model
Recognizing that many small-to-midsize DAM teams struggle with basic metadata hygiene—let alone complex W3C PROV integrations—Brown offers a pragmatic, simplified alternative focused on three core states:
- ACTIVE: Fully cleared, current, and approved for immediate agentic deployment.
- SUPERSEDED: Retained for reference or history, but strictly blocked from automated publishing workflows.
- ARCHIVAL: Stored for compliance or long-term preservation, entirely locked from operational retrieval.
- Supplemental Fields: Mandatory attachment of approved use cases and clear effective dates.
Official Statements and Industry Perspectives
The debate sparked by Brown’s analysis has resonated deeply across the digital asset management, metadata engineering, and enterprise AI communities. Industry leaders and technologists have weighed in on the implications of shifting from reactive provenance to proactive canonical authority.
"The interesting failure was not image generation. It was not even search. The old image was an authentic image of the correct person. Its provenance could have been flawless. The failure was that authenticity had been mistaken for authority."
— Joshua Brown, DAM Strategist and Industry Contributor
Reflecting on the operational realities of implementing these changes, enterprise database architects and DAM consultants have highlighted both the brilliance of the conceptual distinction and the hurdles of execution.
- The Metadata Discipline Challenge: Several veteran DAM administrators have noted that while a five-part state model is philosophically sound, its success relies entirely on human discipline. As one enterprise architect remarked, "If content teams fail to consistently tag basic usage rights today, expecting them to seamlessly maintain complex canonical authority states across millions of generative variants without rigorous automation is exceptionally ambitious."
- The AI Governance Consensus: Artificial intelligence ethicists and workflow automation specialists have largely rallied behind Brown’s concluding staccato:
- “Authentic is not current.”
- “Findable is not approved.”
- “Stored is not publishable.”
Experts argue that as autonomous agents take over the final miles of enterprise content delivery, traditional DAMs can no longer afford to act as passive libraries. They must evolve into active governance engines capable of enforcing hard boundaries on soft intelligence.
Future Outlook: The Road Ahead for Agent-Facing DAM Infrastructure
As organizations accelerate their adoption of agentic AI workflows, the architecture of enterprise content management is undergoing an inevitable reckoning. The casual oversight that leads to an outdated headshot being published in a draft is a harmless symptom of a much deeper vulnerability; left unaddressed, the same systemic flaw could result in compliance violations, copyright infringements, and severe brand erosion at scale.
1. The Convergence of DAM and Policy Engines
In the near future, standalone DAM platforms will increasingly merge with dynamic policy-enforcement engines. Rather than relying on static folder structures or manual tagging, next-generation systems will feature real-time decision layers. When an AI agent requests an asset, the DAM will evaluate not just semantic relevance, but temporal validity, active licensing windows, and hierarchical authority status before granting access.
2. Standardizing Canonical Authority Protocols
Just as C2PA and W3C PROV established baseline trust for content provenance and origin verification, the industry will need to develop unified standards for operational authority. Software vendors, metadata standards bodies, and enterprise buyers must collaborate to establish native schema elements that clearly distinguish between an asset’s historical existence and its present-tense operational permissions.
3. Redefining Metadata Management for Autonomous Systems
For years, metadata hygiene was viewed as an internal housekeeping chore—important for search efficiency, but rarely mission-critical. In the era of autonomous agents, metadata is the primary control plane for corporate governance. Organizations that invest in robust, simplified authority frameworks (such as the Active/Superseded/Archival model) will successfully harness the speed and efficiency of AI. Those that continue to conflate authenticity with authority will find themselves vulnerable to automated errors executed at blinding speed.
Ultimately, the lesson of the misplaced headshot is clear: as machines gain the autonomy to act on our behalf, our systems must be engineered to know not just where a piece of content came from, but whether it truly has the right to speak for us today.