Executive Overview
For decades, the digital marketing ecosystem has been locked in a circular, often contentious debate over attribution models. Growth teams, performance marketers, and finance executives routinely lock horns over the ideological superiority of last-click versus data-driven attribution (DDA). Yet, behind these boardroom arguments lies an inconvenient truth that seasoned data architects and analytics engineers have long understood: most attribution failures have very little to do with the mathematical model itself.
Instead, the rot sits much further down the data stack. Modern e-commerce operations are routinely crippled by fragmented customer journeys that fail to stitch together, touchpoints logged across wildly inconsistent formats and naming conventions, and a massive blind spot regarding ad exposures—particularly impressions from walled gardens—that never make it into the enterprise data warehouse.
When the underlying data infrastructure is fundamentally broken, swapping out an algorithmic model for a heuristic one is akin to rearranging deck chairs on the Titanic. Get the data layer right, and the choice of attribution model becomes a relatively minor downstream decision. Get it wrong, and no machine learning algorithm, neural network, or probabilistic model can save the integrity of the output.
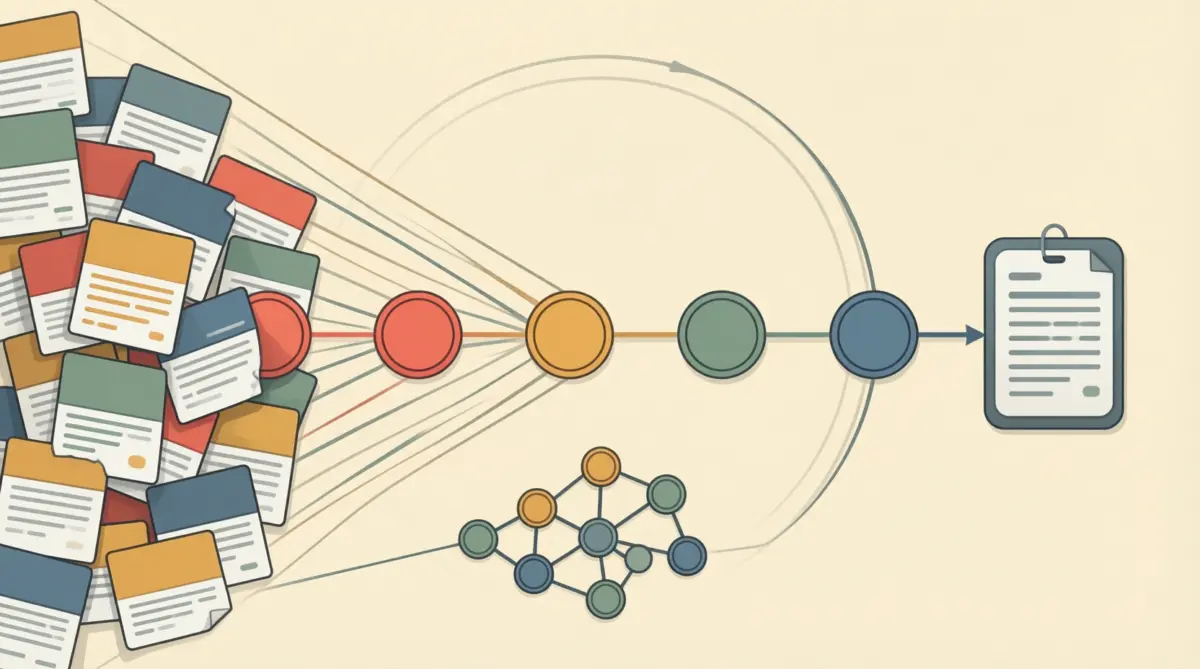
This comprehensive technical walkthrough examines the anatomy of e-commerce attribution failure, detailing a rigorous, step-by-step blueprint for building a resilient, warehouse-native attribution pipeline. Designed specifically for the data engineers and analytics professionals tasked with owning these systems, this guide explores identity resolution, canonical touchpoint tables, server-side signal recovery, and experimental validation.
Detailed Chronology: The Anatomy of an Attribution Pipeline Build
Building a production-grade attribution engine requires a methodical, sequential approach. Skipping steps or bypassing structural data hygiene inevitably leads to cascading discrepancies that erode stakeholder trust.
Step 1: Defining the Boundaries of a Journey
Attribution is, at its mathematical core, the process of assigning credit for a conversion to the preceding touchpoints that influenced it. Before an organization can assign credit, it must establish a strictly enforced, unambiguous definition of both ends of that equation: the conversion and the journey.
- The Conversion Source of Truth: Conversions must always originate from the enterprise order management system (OMS), point-of-sale (POS) data, or centralized CRM—never from ad platform pixels. Advertising platforms (such as Meta, Google, TikTok, and Pinterest) utilize proprietary counting rules, opaque attribution windows, and overlapping claims logic designed to make every platform look indispensable. Your internal order table is the single source of truth that the entire enterprise can agree upon.
- The Journey Window: A journey is defined as the ordered set of touchpoints belonging to the same resolved customer profile within a strictly bounded lookback window. For the vast majority of e-commerce brands, a lookback window spanning 30 to 90 days accurately captures the realistic consideration and conversion cycle. Crucially, data teams must pick one window and apply it universally. Implementing channel-specific lookback windows (e.g., 7 days for paid search, 28 days for paid social) is one of the quietest, most destructive ways to introduce systemic bias into your attribution outputs.
Step 2: Identity Resolution (Stitching Before Counting)
A customer who discovers a brand via mobile browser, clicks a retargeting email on a laptop weeks later, and ultimately converts inside a dedicated native mobile app will appear as three entirely distinct, disconnected individuals to a naive analytics tool. Identity resolution is the unglamorous, foundational core of modern attribution.
To construct a reliable identity graph, data teams must layer multiple keys together:
- Deterministic Identifiers: Authenticated user IDs, hashed email addresses, and phone numbers captured during checkout or login events.
- Probabilistic Identifiers: First-party cookies, device fingerprints, and IP-to-user-agent mappings bound together via time-decay confidence scores.
This requires maintaining a dedicated identity graph table within the data warehouse that explicitly logs which identifiers belong to a specific customer profile and the exact timestamp when each link was established. When downstream stakeholders inevitably question a strange attribution result, having the ability to transparently trace how a specific customer journey was assembled will save engineering teams days of painful debugging.
Leveraging Data Clean Rooms for Cross-Company Measurement
While internal identity graphs resolve customer links across your owned properties, measuring advertising impact across external publisher boundaries introduces a new hurdle: connecting ad exposure to purchases without illegally exchanging raw, unhashed customer records.
Data clean rooms have evolved from theoretical panel discussions into proven, widely adopted enterprise technologies. As Peter Nummerdor, VP at Videoamp, notes: "Clean rooms have moved from a topic the industry pontificated about on panels, to a proven and widely adopted technology."
Clean rooms enable privacy-preserving collaboration for closed-loop attribution, media mix modeling (MMM) data feeds, and cross-publisher measurement. However, data teams must maintain strict operational boundaries:
- Separate Aggregates from Deterministic Links: Audience overlap metrics generated in a clean room should remain strictly aggregated. Never inject unverified probabilistic scores into your core deterministic identity graph.
- Document Metadata: Record the specific measurement window and clean room query that produced external data feeds, enabling downstream analysts to reproduce comparisons without treating aggregate estimates as observed user-level touchpoints.
Step 3: Constructing the Canonical Touchpoint Table
Every single interaction—whether a paid ad click, an email open, an organic search visit, or an affiliate referral—must ultimately land in a single, highly structured table adhering to a strict, standardized schema.
| Field Name | Data Type | Purpose & Description |
|---|---|---|
customer_id |
STRING / UUID | The globally resolved enterprise identity derived directly from the identity graph. |
timestamp |
TIMESTAMP (UTC) | The precise moment the event occurred, standardized to Coordinated Universal Time. |
channel |
VARCHAR | Standardized channel taxonomy (e.g., paid_social, paid_search), stripped of raw UTM noise. |
campaign |
VARCHAR | Mapped campaign identifier sourced from enterprise naming conventions. |
touch_type |
ENUM | Categorization of the interaction: click, impression, visit, email_open, etc. |
cost |
NUMERIC | Financial cost associated with the touchpoint, utilized downstream for ROAS calculations. |
Taming the Taxonomy Problem
The channel field requires significantly more architectural governance than most teams anticipate. Human-generated UTM parameters are notoriously messy. Variations such as facebook, Facebook_Ads, fb-paid, and meta must be programmatically normalized into a single canonical value before entering any attribution model. Relying on a centrally maintained mapping table or dimension table within the warehouse is vastly superior to maintaining brittle, unmanageable SQL CASE statements.
Step 4: Accounting for Unobserved Impressions
This is the exact juncture where the vast majority of in-house attribution builds stall. Tracking clicks is straightforward; tracking ad impressions generated inside walled gardens (Meta, TikTok, Snapchat, Amazon) is intentionally restricted, as these platforms rarely share granular, user-level exposure logs.
Yet, for modern e-commerce brands, paid social advertising operates primarily through visual exposure. Consumers routinely view an ad, do not click, and subsequently navigate directly to the store or search for the brand name days later. Ignoring these unobserved impressions systematically overcredits search and direct traffic—the exact channels that harvest demand created elsewhere in the funnel.
Recovering Signals via Server-Side Tracking
Missing purchase events and missing ad impressions require entirely distinct engineering fixes. Industry research indicates that traditional browser-side pixels routinely miss between 30% and 50% of conversion events due to ad blockers, Intelligent Tracking Prevention (ITP), and privacy regulations.
Implementing server-side tracking—such as Meta’s Conversions API (CAPI) or server-side Google Tag Manager (sGTM)—utilizing strict event_id deduplication is mandatory. When a purchase event is dispatched via both browser and server pathways, maintaining a consistent event_id allows the destination platform and your warehouse to recognize the payloads as a single event.
However, engineers must remain vigilant: sending conversion events from the server fixes missing conversion data; it does not magically supply the user-level impression history absent from your warehouse.
To handle unobserved impressions without breaking your attribution logic, data teams generally rely on two primary architectural strategies:
- Media Mix Modeling (MMM) Calibration: Using top-down econometric models to estimate the baseline influence of unclickable upper-funnel impressions and scaling down channel credit accordingly.
- Probabilistic Exposure Modeling: Injecting synthetic impression touchpoints based on frequency, reach, and historical decay curves.
Whichever path is chosen, modeled touchpoints must be explicitly flagged in the canonical touchpoint table (is_modeled = TRUE), ensuring analysts can effortlessly segregate observed deterministic data from estimated probabilities.
Step 5: Implementing an Explainable Attribution Model
Once clean, stitched journeys and standardized touchpoints reside in the warehouse, executing the attribution model is the easiest phase of the pipeline. Common algorithmic options include:
- Markov Chain Models: Calculating transition probabilities between marketing channels to determine the removal effect of each touchpoint.
- Shapley Value Attribution: Applying cooperative game theory to fairly distribute conversion credit based on every possible coalition of marketing channels.
While algorithmic models reflect reality with higher fidelity, they are notoriously difficult to explain to a skeptical Chief Marketing Officer or finance team. A proven operational compromise is to run a transparent rule-based model (such as Time-Decay or U-Shaped) concurrently with an advanced algorithmic model, investigating instances where the two outputs diverge sharply.
Step 6: Validating Against Causal Experiments
Attribution models are ultimately sophisticated estimations. They must be continuously audited against independent, ground-truth methodologies. Geo-holdout tests, conversion lift studies, and planned budget pauses produce rigorous causal reads for individual channels.
If your multi-touch attribution model dictates that paid social drives 40% of enterprise revenue, but a strict geographic holdout test shows zero statistical variance in sales when paid social spend is completely switched off in targeted regions, the model requires urgent recalibration, not aggressive defense. Data teams should mandate at least one rigorous validation test per quarter for their largest customer acquisition channels.
Supporting Context & Metrics: Reconciling Platform Claims vs. Reality
One of the most immediate symptoms of a broken attribution data layer is the "Dashboard Discrepancy Crisis." If you sum the conversion metrics reported natively across Meta, Google, TikTok, and Pinterest dashboards, you will almost invariably find that ad platforms claim credit for significantly more orders than your business actually fulfilled.
[Meta Dashboard: 1,200 Conversions]  ──┐
[Google Dashboard: 950 Conversions]  ──┼──> Sum: 2,850 "Claimed" Conversions
[TikTok Dashboard: 700 Conversions]  ──┘
                                                VS.
                                       [Shopify/OMS: 650 Actual Sales]
This occurs because every walled garden utilizes proprietary attribution windows, view-through credit windows, and non-exclusive counting logic. Pantosource and other e-commerce analytics firms frequently document instances where platforms claim thousands of sales against a few hundred actual transactions.
To resolve this, warehouse-native pipelines must decouple platform-reported metrics from order-level reconciliation:
- Match raw conversion logs directly against order IDs in your ERP or OMS.
- Preserve original platform totals as distinct, unadjusted monitoring metrics rather than forcing them into your attribution math.
- Analyze attribution credit strictly through shared journey records to establish true incrementality.
Official Statements & Industry Perspectives
The structural shift toward warehouse-native attribution and privacy-safe measurement has garnered widespread commentary from industry leaders navigating the post-cookie landscape.
Addressing the evolution of cross-platform measurement infrastructure, Peter Nummerdor, VP at Videoamp, emphasizes the operational maturity of modern data collaboration:
"Clean rooms have moved from a topic the industry pontificated about on panels, to a proven and widely adopted technology."
As data teams grapple with the integration of server-side APIs, industry analysis from engineering groups like Digital Applied highlights the stark realities of modern signal loss:
"Browser pixels routinely miss 30% to 50% of conversions, necessitating robust server-side tracking pipelines utilizing event_id deduplication to safeguard core data collection."
These perspectives underscore a unified industry consensus: relying on client-side marketing pixels is no longer viable. Enterprise data engineering teams must take ownership of the underlying capture mechanisms to ensure analytical integrity.
Future Outlook: The Next Evolution of E-Commerce Attribution
As privacy regulations tighten, browser cookies vanish entirely, and machine learning tooling matures, the future of e-commerce attribution will undergo a profound transformation.
1. The Convergence of MTA and MMM
Historically, Multi-Touch Attribution (MTA) (bottom-up, user-level journey tracking) and Media Mix Modeling (MMM) (top-down, macro-economic regression analysis) operated in entirely separate silos. The future belongs to Unified Measurement Frameworks, where warehouse-native pipelines feed granular user-level touchpoint data directly into Bayesian structural time-series models. This bridges the gap between unobserved upper-funnel impressions and deterministic conversion paths.
2. Automated Anomaly Detection in Data Layers
As pipelines ingest millions of touchpoints from disparate APIs, data engineering teams will increasingly deploy automated data observability tools. These systems will autonomously detect schema drift, UTM taxonomy pollution, and pixel dropouts before they silently corrupt downstream attribution reports and distort multi-million-dollar budget allocations.
3. Real-Time Causal Optimization
Moving beyond static lookback windows and retrospective monthly reporting, next-generation attribution engines will leverage streaming data architectures (utilizing tools like Apache Kafka, Flink, and warehouse-native streaming tables) to calculate real-time marginal ROAS. This will allow automated bidding systems to shift capital dynamically based on verified, incremental lift rather than delayed platform-reported heuristics.
Final Recommendation: Check Your Pipeline Before Changing Budgets
Attribution is fundamentally a data engineering challenge that features a statistical modeling step at the very end. Stitch your customer identities with rigorous care, standardize your touchpoint taxonomy into a single canonical table, maintain absolute transparency regarding unobserved ad exposures, and relentlessly validate your outputs against independent causal experiments.
Teams that master this foundational architecture rarely find themselves arguing about attribution models in executive meetings, because the underlying data has already settled the debate.