In the high-stakes world of machine learning engineering, data is no longer merely an input; it is the fundamental currency of competitive advantage. For years, organizations operated under a simple premise: the more data ingested, the smarter the predictive model. However, as foundation models scale and production environments grow increasingly complex, raw volume has taken a backseat to data provenance, quality, and structural integrity.
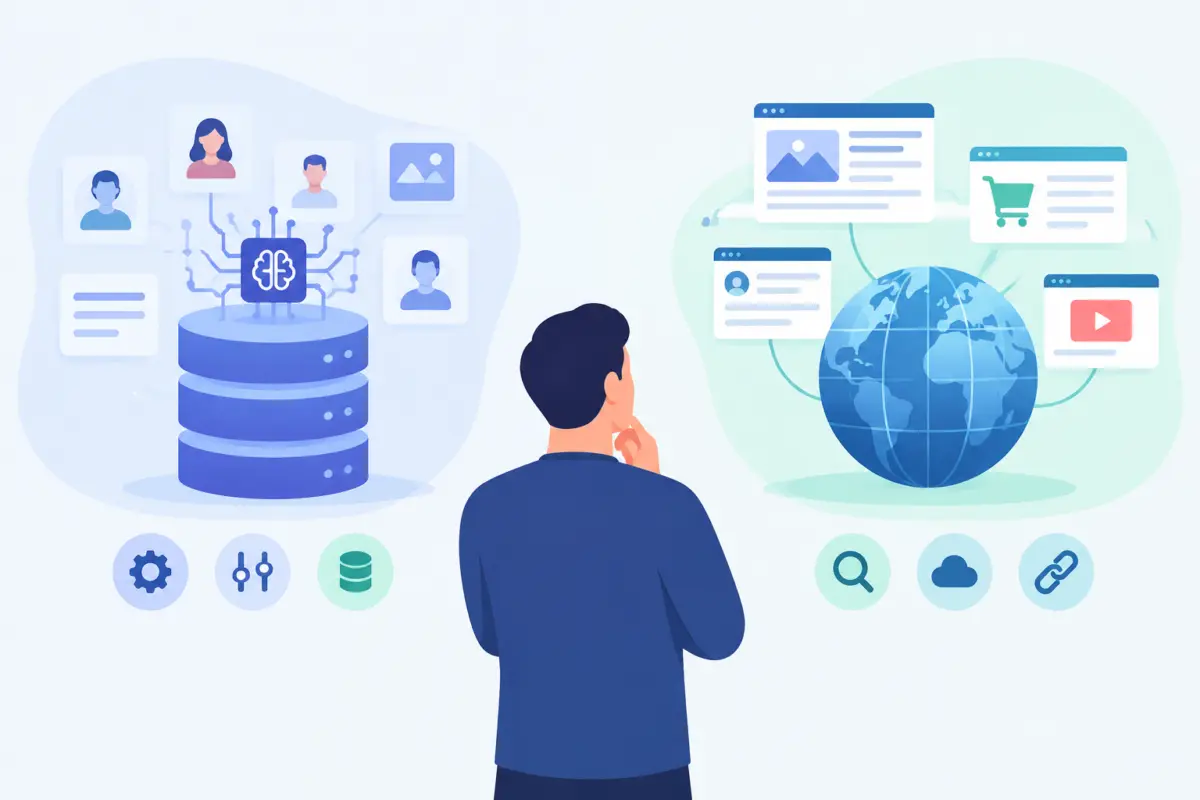
Today, data science teams find themselves navigating a critical bifurcation in data strategy. On one side lies real web data—the messy, chaotic, yet undeniably authentic record of human behavior, market shifts, and live observations captured across the digital landscape. On the other side sits synthetic data—an on-demand, algorithmic sandbox that allows engineers to build, stress-test, and scale machine learning models without the prohibitive costs of manual labeling or the privacy liabilities of scraping live web pages.
For many organizations, the knee-jerk reaction has been to treat these two data modalities as interchangeable commodities designed to fill training pipelines. This approach is fundamentally flawed. Real web records and synthetic generations solve entirely different engineering problems. While synthetic simulations provide an invaluable environment for stress-testing edge cases, they cannot replace ground truth.
This comprehensive guide examines the operational trade-offs, limitations, and collection methodologies governing both real and synthetic data. By exploring how elite engineering teams fuse these two methodologies into a continuous, closed-loop feedback pipeline, we uncover the strategies required to build resilient, production-ready artificial intelligence systems.
Executive Overview: The Architecture of Modern AI Data Pipelines
The modern machine learning lifecycle is defined by a paradox. Algorithms require massive amounts of diverse training data to generalize effectively, yet the public internet—once viewed as an infinite, homogenous repository of knowledge—is undergoing structural changes. As AI-generated content proliferates across public web domains, the internet is increasingly consuming its own digital exhaust.
When models train recursively on machine-generated data, they fall victim to well-documented degenerative cycles. To break this loop, engineering leadership must adopt a nuanced taxonomy of data types.
Defining the Boundaries: Real vs. Synthetic Data
- Real Web Data: Captures observable, historical events anchored in actual space and time. Whether logging a sudden e-commerce price drop on a major retail platform, tracking volatile hiring surges across enterprise job boards, or monitoring shifts in public sentiment, real web data documents what actually happened. It carries an objective observation timestamp and reflects the chaotic friction of the physical and digital economy.
- Synthetic Data: Operates as an experimental playground. Generated through algorithmic distributions, parametric rules, or generative models, synthetic records allow engineers to manufacture scenarios that rarely appear in historical logs. Teams can artificially simulate catastrophic card-not-present fraud spikes, test supply chain logistics under localized chokepoints, or balance severely underrepresented classes.
However, the distinction goes beyond mere generation mechanics. Real web records anchor a model in operational reality. Synthetic records reflect the mathematical assumptions of their underlying generators. When customer habits shift unpredictably, relying solely on synthetic assumptions exposes organizations to catastrophic production drift.
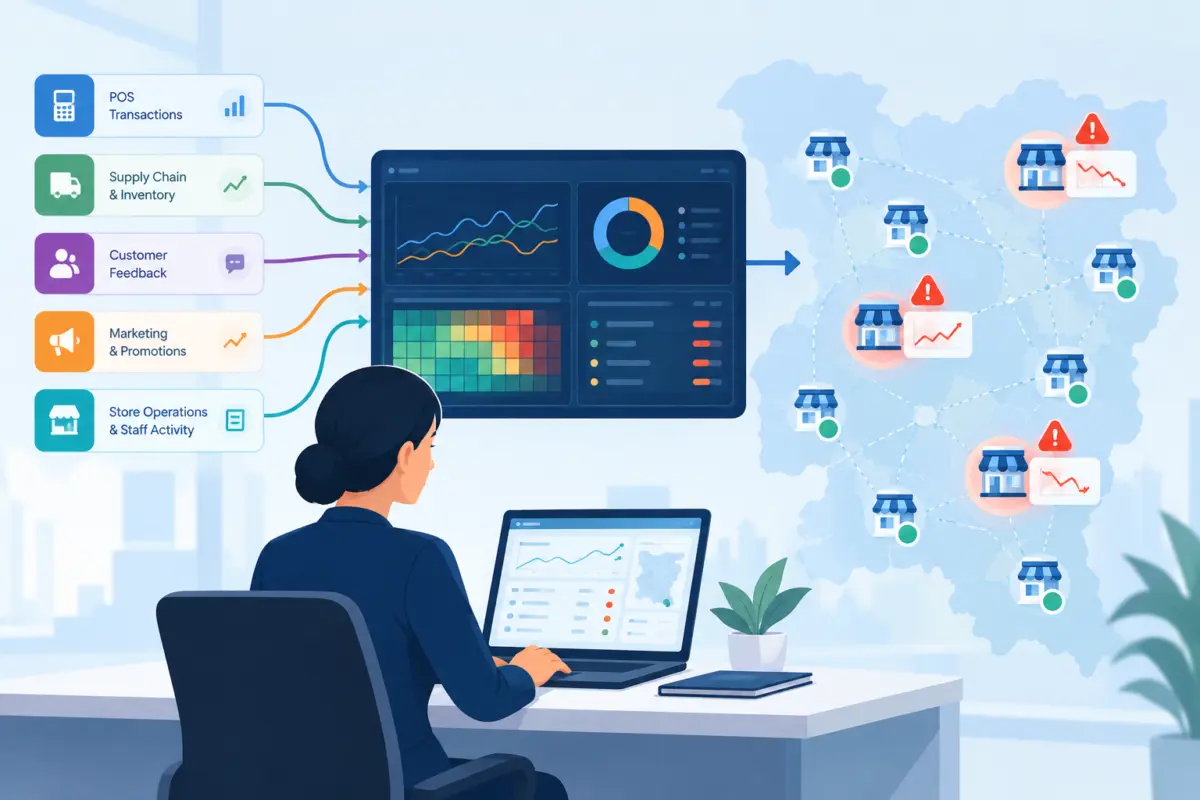
Consequently, high-performing engineering teams do not choose between the two. They build sophisticated, multi-tiered architectures where live web telemetry detects shifts in the wild, synthetic data generators manufacture targeted corner cases around those new patterns, and rigorous validation loops ensure the retrained model withstands unmanipulated real-world inputs.
Detailed Chronology: The Evolution of Data Collection and Synthetic Generation
To understand how enterprise data strategy reached this critical crossroads, it is helpful to examine the historical trajectory of data acquisition, the rise of synthetic modeling, and the regulatory and technical milestones that shaped the current paradigm.
Phase 1: The Era of Unfiltered Web Harvesting (Early 2010s – 2018)
In the early days of deep learning, web scraping was largely viewed as an open-ended harvesting operation. Organizations deployed basic scripts to ingest vast quantities of unstructured text, images, and tabular data from public forums, e-commerce sites, and directories. Little attention was paid to data provenance, consent, or structural noise. The prevailing engineering philosophy was straightforward: scale cures all ills. If a model encountered errors, throwing more raw scraped data at the problem typically resolved performance plateaus.
Phase 2: The Compliance and Quality Reckoning (2019 – 2022)
As global privacy regulations—such as the European Union’s General Data Protection Regulation (GDPR) and the California Consumer Privacy Act (CCPA)—matured, the legal landscape surrounding web data collection shifted dramatically. Enterprises could no longer casually scrape personally identifiable information (PII) or ignore website terms of service. Concurrently, the computational cost of cleaning, parsing, and manually labeling unstructured web data soared. Organizations began seeking alternative ways to train models without incurring massive annotation overheads, sparking initial enterprise experiments in synthetic data generation.
Phase 3: The Generative Boom and the Threat of Model Collapse (2023 – Present)
With the advent of powerful generative architectures, synthetic data transitioned from a niche testing tool to a primary training vector. Enterprises realized they could simulate rare edge cases, augment sparse datasets, and protect user privacy by training models on artificial records.
However, this boom introduced unforeseen mathematical hazards. As the public internet filled with synthetic text, images, and code, researchers began observing the degradation of models trained on AI-generated outputs. A landmark study published in Nature in July 2024 by Ilia Shumailov and colleagues formally demonstrated the phenomenon of model collapse: when generative models are trained recursively on model-produced content, statistical tail events vanish over successive generations, causing outputs to degenerate into repetitive, low-variance noise. This historical turning point cemented the realization that synthetic data, while powerful, requires strict grounding in empirical, real-world observations.
Supporting Context & Metrics: Unpacking the Limitations of Synthetic Data
While synthetic data offers undeniable advantages in scalability and cost efficiency, relying on it as an unmonitored training foundation introduces severe operational risks. Engineering teams must navigate three primary hazards: metric illusion, distorted event distributions, and unverified causality.
1. The Metric Illusion and Algorithmic Echo Chambers
A synthetic data generator operates by learning the internal statistical patterns of a seed dataset and reproducing them under randomized parameters. When an engineering team trains and evaluates a machine learning model on data originating from that same generator, the model naturally excels.
High accuracy scores on a synthetic test set, however, often measure compatibility with the generator rather than readiness for live production traffic. The model learns to master the subtle mathematical artifacts of the generation process rather than genuine market mechanics. In production, this illusion shatters the moment the model encounters the messy, uncurated friction of the real world.
2. Distorted Event Distributions and False Positives
Synthetic data allows engineers to manufacture thousands of examples of rare phenomena—such as fraudulent transactions, rare medical pathologies, or extreme inventory stockouts. While this practice successfully balances sparse classes, it artificially skews the base rate of occurrence.
In a production environment, an over-indexed sensitivity to anomalies leads directly to a surge of false positives. For instance, an anti-fraud model trained on heavily oversampled synthetic fraud records may flag legitimate customer transactions at an unsustainable rate, resulting in abandoned carts, frustrated users, and costly manual review queues. Synthetic data excels at illustrating what an anomaly looks like, but it fails to establish how often that anomaly occurs in nature.
3. Unverified Causality and Strategic Blunders
Causality represents one of the most stubborn hurdles in synthetic modeling. Consider a synthetic table indicating that lowering a product price by 10% yields a 30% increase in sales volume. In a machine-generated environment, this correlation appears ironclad.
However, that synthetic relationship may merely reflect unmodeled seasonal holidays, macroeconomic shifts, or temporary supply chain shortages embedded within the original seed data. If an enterprise executive acts on this simulated correlation in a dynamic, highly volatile market, an unverified assumption quickly transforms into an expensive pricing blunder.
Furthermore, curating a synthetic dataset directly encodes organizational bias and business logic. By deciding which scenarios to oversample and which failure modes to suppress, data teams subconsciously dictate how the model will allocate risk in production.
Official Statements and Industry Insights: The Enterprise Perspective
As enterprises race to deploy production-grade artificial intelligence, industry analysts and research institutions are issuing stark warnings regarding the quality of data inputs. The consensus across the enterprise landscape is clear: the bottleneck in big data engineering has officially shifted from raw volume to verified provenance.
The Cost of AI-Ready Data Deficits
According to comprehensive research published by Gartner in early 2025, organizations will abandon 60% of AI projects that lack foundational, AI-ready data through 2026. The report emphasizes that algorithmic sophistication cannot compensate for corrupted, unverified, or structurally flawed training inputs. Clean, audited source data remains a non-negotiable prerequisite for enterprise machine learning success.
Furthermore, academic consensus—underscored by the aforementioned research from Shumailov et al. (2024)—warns that unchecked reliance on synthetic generation without empirical anchoring inevitably leads to the erosion of model diversity. Industry leaders are increasingly recognizing that synthetic data must be treated as a precision surgical instrument rather than a blunt instrument for filling empty data warehouses.
How to Collect Real Web Data: A Multi-Channel Enterprise Strategy
Because real-world observability is essential for grounding predictive models, engineering teams must establish robust, compliant, and scalable data collection pipelines. Selecting the appropriate acquisition channel depends entirely on an organization’s latency requirements, governance standards, and engineering capacity. Mature data organizations typically blend four primary ingestion channels:
[Enterprise Data Strategy]
       │
       ├─► 1. Open Public Repositories (Baselines & Macro Trends)
       ├─► 2. Commercial Data Vendors (Rapid Prototyping & Historical Archives)
       ├─► 3. Direct API Integrations (Structured, Low-Latency Feeds)
       ├─► 4. Custom Scrapers & Managed Partners (Niche Catalogs & Edge Data)
       │
       └─► [Closed Feedback Loop: Real Telemetry ➔ Synthetic Augmentation ➔ Validation]
1. Open Public Repositories
Government portals, international registries, and academic databases (such as data.gov, Eurostat, and World Bank datasets) offer free access to official economic indicators, demographic registries, and macro-level baselines.
- Use Case: Initial model benchmarking and macroeconomic forecasting.
- Trade-offs: While cost-effective, engineering teams must rigorously scrutinize license terms, field completeness, and update cadences. Stale open records frequently introduce latent drift into production pipelines.
2. Commercial Data Vendors
Third-party commercial vendors package point-in-time snapshots and historical archives, often delivered via recurring subscription feeds.
- Use Case: Rapid prototyping, market research, and establishing historical baselines without building infrastructure from scratch.
- Trade-offs: Teams sacrifice control over underlying data schemas and collection windows. Critical proprietary signals required for competitive differentiation are often omitted from packaged commercial datasets.
3. Direct API Integrations
Direct API integrations deliver structured JSON, CSV, or Parquet feeds directly from target platforms without the overhead of parsing raw HTML.
- Use Case: Ingesting structured, high-frequency data streams such as financial feeds, inventory statuses, or official platform metrics.
- Trade-offs: Enterprise rate limits and payload quotas can restrict ingestion velocity. Furthermore, upstream endpoint modifications or schema changes can break downstream feature pipelines without warning.
4. Automated Custom Web Scrapers and Managed Partners
Building automated ingestion pipelines using headless browser frameworks (such as Playwright, Puppeteer) or distributed crawling engines (such as Scrapy) gives engineering teams absolute control over data intake.
- Use Case: Extracting niche competitor catalogs, localized pricing data, and unstructured web content tailored precisely to model feature specifications.
- Trade-offs: Maintaining scrapers at scale requires constant engineering overhead to bypass operational roadblocks, including Cloudflare bot detection challenges, IP rate-limiting, and dynamic JavaScript rendering.
To mitigate these engineering bottlenecks, many enterprises partner with managed web scraping providers. An external partner handles proxy rotation, navigates complex anti-bot mechanisms, and manages schema drift when target websites alter their layouts, delivering clean, structured records directly into the organization’s data warehouse.
Future Outlook: The Closed-Loop Enterprise AI Pipeline
As we look toward the future of enterprise artificial intelligence, the dichotomy between real and synthetic data will continue to evolve. The most successful organizations will abandon the false choice of prioritizing one modality over the other. Instead, competitive advantage will belong to teams that successfully integrate both into a continuous, agile, and self-correcting feedback loop.
The Anatomy of the Closed Feedback Loop
- Detection: Live, real-world web data acts as the sensory nervous system, continuously monitoring the external environment to detect genuine shifts in market dynamics, competitor behavior, and user sentiment.
- Simulation: When novel patterns or rare anomalies are detected in the wild, engineers deploy synthetic data generation pipelines to manufacture targeted corner cases, stress-testing model resilience around the newly observed phenomena without manual labeling bottlenecks.
- Validation: Before deployment, the retrained model undergoes rigorous out-of-sample testing against unmanipulated, real-world inputs to verify that operational performance holds true under production conditions.
Ultimately, context dictates utility. A synthetically generated review on an e-commerce platform is invaluable if an organization’s goal is analyzing automated bot spam patterns in search results; that same review is utterly useless if the team is evaluating genuine customer sentiment regarding product durability. Similarly, a scraped retail price reflects what an e-commerce platform served to a specific IP address in a specific geographic region at a precise second—not a universal economic truth.
By understanding the distinct functional roles of online data and establishing robust collection and simulation infrastructure, engineering teams can prevent synthetic simulations from masquerading as empirical ground truth. In doing so, they lay the foundation for robust, trustworthy, and enduring enterprise AI systems.